Use an SSD as VRAM to run a 744B model on a laptop
The open-source inference engine Colibrì tiers MoE expert weights across VRAM, RAM, and SSD storage, enabling consumer-grade PCs to run 744B-parameter GLM models. It proves that such models can “fit,” but efficient, practical use remains a long way off.
A 744B Model Squeezed into 25GB of Memory
An open-source inference project called Colibrì has recently attracted developers’ attention: it attempts to run a GLM-series MoE model with roughly 744 billion total parameters on a consumer-grade computer with no data-center-class GPU, only about 25GB of available memory, and an NVMe SSD.
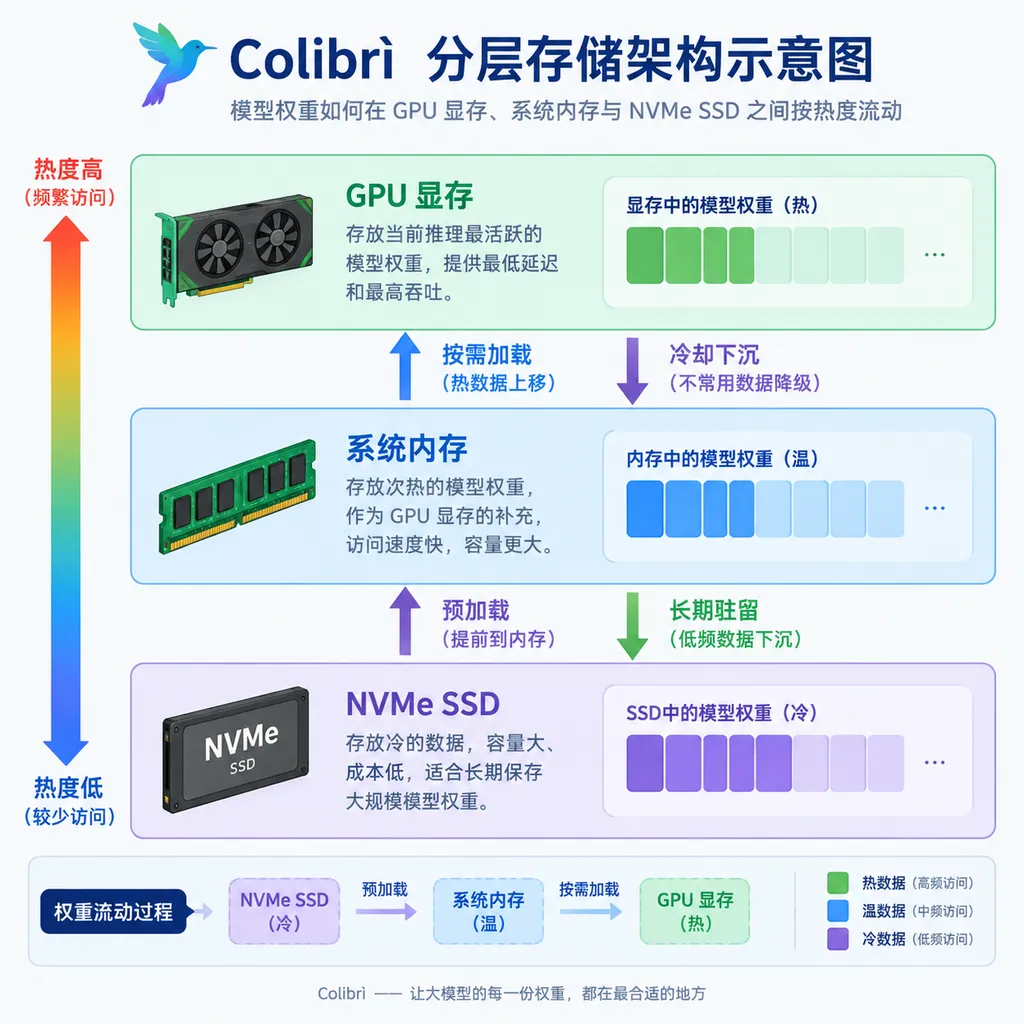
Its most eye-catching claim is that it “uses an SSD as VRAM.” This wording is not strictly accurate, but it captures the project’s core idea—Colibrì no longer requires all model weights to reside in VRAM or RAM simultaneously. Instead, it combines VRAM, RAM, and NVMe SSD storage into a hierarchical weight-storage system. Frequently accessed weights are placed on faster devices, while rarely used experts remain on disk and are loaded only when needed.
This does not literally turn an SSD into VRAM. SSD latency, bandwidth, and access granularity cannot compare with those of VRAM. A more accurate description is: Colibrì incorporates SSD storage into the model-inference weight-scheduling path, trading speed for capacity so that a model that otherwise could not fit at all can at least run.
This is also where the project’s real value lies. It does not solve the problem of “how to run a 744B model quickly on a laptop,” but a more fundamental one: must an enormous MoE model reside entirely in expensive high-speed memory? Colibrì’s answer is: not necessarily.
It Runs Because of MoE, Not Just the SSD
If this were a dense 744B-parameter model, merely storing the weights on an SSD would not work miracles. Even with 4-bit quantization, the model would remain enormous, and generating each token could require scanning a vast amount of weight data, quickly turning I/O into an unacceptable bottleneck.
Colibrì is viable primarily because it relies on a Mixture of Experts (MoE) architecture.
Although MoE models have enormous total parameter counts, each forward pass activates only a subset of their experts. An internal router selects a small number of experts to participate in computation based on the current token’s hidden state. The remaining experts count toward the model’s total parameters but do not need to be involved in that computation step.
You can think of it as a consulting firm with hundreds of specialists: its staff directory is enormous, but when handling a specific problem, the receptionist calls in only a few relevant experts rather than bringing everyone into the meeting room at once.
According to currently available public descriptions, the 744B-class model targeted by Colibrì activates far fewer parameters per token than its total parameter count. Frequently used components such as attention layers, embedding layers, and shared experts can be quantized and kept resident in RAM. The vast number of routed experts are stored separately on the SSD and loaded into memory for computation only when selected by the router.
Its simplified execution logic looks roughly like this:
Load resident weights into RAM
Initialize expert cache

for token in generation:
    for layer in model:
        Compute attention and routing
        selected = small set of experts chosen by router

        if selected is not in RAM/VRAM cache:
            Asynchronously read expert weights from NVMe SSD

        Execute selected experts
        Update expert access frequency and LRU cache
        Prefetch experts likely to be used by the next layer

    Output token
In this process, the user experience is determined not by SSD capacity but by two questions: how much data must actually be read for each token, and whether those reads can overlap with CPU or GPU computation.
What It Actually Does Is “JIT for Model Weights”
Colibrì compares its approach to JIT compilation, and the analogy is quite accurate.
Traditional JIT systems do not optimize every possible program path in advance. Instead, they observe which code actually executes at runtime and concentrate resources on hot paths. Colibrì applies a similar approach to model weights: rather than requiring every expert to remain resident at all times, it records expert-routing history, keeps frequently used experts in faster storage tiers, and gradually evicts cold experts back to the SSD.
From fastest to slowest, the hierarchy can be roughly divided into:
- VRAM: Stores the most frequently accessed and latency-sensitive weights;
- RAM: Holds resident layers and popular experts with high cache hit rates;
- NVMe SSD: Stores the vast majority of experts that are not currently being used;
- Prefetch queue: Loads experts likely to be selected in advance based on routing history or correlations between adjacent layers.
The project also introduces mechanisms such as per-layer LRU caches, hot expert pinning, routing history, and expert prefetching. LRU evicts the least recently used experts; hot expert pinning prevents frequently accessed weights from repeatedly moving in and out of memory; and prefetching attempts to load the next layer’s experts while the current layer is being computed, hiding some I/O latency behind computation.
Colibrì does not refuse to use a GPU when one is available. It continues to move frequently accessed weights into VRAM and accelerates computation through CUDA or Metal. When RAM and VRAM are sufficient to hold the set of experts involved in the current task, the SSD may even drop out of the decoding critical path.
Colibrì is therefore not quite the same as an ordinary “run a large model on the CPU” project. It aims to build a unified MoE inference hierarchy spanning SSD storage, RAM, CPUs, and GPUs: on weaker hardware, more weights are pushed down to the SSD; on stronger hardware, more hot weights are promoted to RAM or VRAM.
2,400 Lines of Pure C: Both a Strength and a Limitation
Available materials describe Colibrì as a pure-C inference engine with a core codebase of roughly 2,400 lines. It does not depend on Python and does not require BLAS or a GPU.
A small, direct implementation is well suited to validating system assumptions. Developers can see how model files are mapped, how experts are loaded, when cache hits occur, and whether token generation is bottlenecked by computation or I/O—without first having to navigate an entire complex framework.
However, “pure C” and “zero dependencies” should not automatically be equated with better performance. Much of the code in mature inference frameworks is not mere overhead; it includes years of optimization for different CPU instruction sets, GPU kernels, memory layouts, batching, and concurrent scheduling. Getting a model running in just over two thousand lines of code is an elegant engineering prototype. Turning it into a stable, general-purpose, high-throughput production engine is another undertaking entirely.
For now, Colibrì is better viewed as an executable systems paper than as a direct replacement for vLLM, SGLang, or llama.cpp.
“It Runs” and “It Is Usable” Are Orders of Magnitude Apart
The aspect of Colibrì most prone to misunderstanding is the tendency to interpret “it can run” as “it runs smoothly.” The difference is substantial.
Published test figures claim that on a system with roughly a 12-core CPU, 25GB of memory, and NVMe storage, the model can complete its initial load in about 30 seconds, use approximately 9.9GB of resident memory, and peak at around 20GB during chat. With a cold cache, however, generating each token may require reading roughly 11GB of data from disk, producing only about 0.05 to 0.1 tokens per second.
In other words, a single token may take 10 to 20 seconds. Even if a faster SSD, more memory, cache warming, and speculative decoding could raise performance to around one token per second, the interactive experience would still be nowhere near that of mainstream cloud inference services.
The bottlenecks are also straightforward:
- SSD bandwidth is limited. PCIe 4.0 NVMe sequential read speeds may look impressive, but access to expert weights does not always consist of ideal large, contiguous reads;
- Random access introduces latency. When numerous experts are stored separately, file layout and request coalescing directly affect throughput;
- Cache hits depend on request distribution. Popular experts may repeatedly hit the cache during an extended discussion of related topics, but an abrupt task change may invalidate the cache;
- Single-request and batched workloads conflict. Scheduling strategies optimized for personal local chat may not suit concurrent multi-user services;
- SSD longevity must be monitored. Inference is primarily read-intensive, so write pressure is lower than with training checkpoints, but the heat, throttling, and durability implications of sustained heavy access still cannot be ignored.
Colibrì’s value, therefore, is not that it turns an ordinary laptop into an inference server, but that it lowers the hardware threshold from “cannot start at all” to “can be studied, validated, and executed slowly.”
The Memory Wall Is What Really Matters
Over the past few years, the default approach to deploying large models has been: if there is not enough VRAM, quantize the model; if that is still insufficient, add more GPUs. Colibrì represents another path—accept that high-speed memory will always be scarce, then design the system to dynamically schedule around that scarcity.
This approach is particularly important for future large-scale MoE models. As the total number of experts increases, a model’s logical capacity can expand rapidly without a proportional increase in the number of parameters activated during each inference step. If all experts must still reside in HBM, many weights will spend most of their time merely waiting in expensive GPU memory.
The question Colibrì raises is therefore more important than “running a 744B model on a laptop”:
When each token uses only a small part of the model, why must the entire model be loaded into high-speed memory first?
This resembles the virtual-memory model used by operating systems. Applications see a unified address space, while the underlying system moves pages among caches, memory, and disks based on access frequency. Future model runtimes may adopt a similar mechanism, except that the scheduling units would be experts, tensor blocks, or computation-graph branches rather than memory pages.
The problem is that traditional virtual memory handles programs with relatively strong access locality, while MoE routing is jointly determined by input content and model state. Whether expert selection can be predicted accurately will directly determine whether hierarchical inference becomes an engineering breakthrough or merely a demonstration that is constantly waiting on the SSD.
Suitable for Research and Privacy-Sensitive Scenarios, Not as a Cloud-Service Replacement
Realistic current use cases for Colibrì include:
- Locally validating the structure and outputs of enormous MoE models without renting a multi-GPU server;
- Latency-insensitive offline analysis, long-running batch processing, and experimental agents;
- Infrequent scenarios where data cannot leave the local machine but the task genuinely requires the capabilities of a large model;
- Research into expert caching, prefetching algorithms, quantization formats, and heterogeneous storage scheduling;
- Testing the “minimum viable hardware boundary” of a model across different hardware configurations.
It is not suitable for online services requiring low time-to-first-token latency, consistently high throughput, or multi-user concurrency. For most developers, directly calling a cloud API or deploying a smaller quantized model remains more economical and reliable. OpenAI-compatible aggregation services such as OpenAI Hub are also better suited to application development that requires quickly switching among models such as GPT, Claude, Gemini, and DeepSeek. Colibrì addresses systems experimentation for local inference with enormous MoE models; the two are not competing in the same arena.
A Meaningful “It Runs,” Not a Performance Myth
The best thing about Colibrì is that it does not pretend an SSD can catch up with HBM. What the project demonstrates is that, given a sufficiently sparse activation structure combined with quantization, caching, prefetching, and hierarchical scheduling, a model’s total parameter count no longer has to be tightly bound to the machine’s high-speed memory capacity.
Its greatest current shortcomings are equally clear: cold-cache disk traffic is excessive, generation is very slow, and model compatibility, output accuracy, and cross-platform stability still require more extensive independent testing. Existing performance figures largely come from project descriptions and media reports and should not be treated as standardized benchmarks.
Even so, this remains a direction worth watching for developers. The next round of large-model inference optimization may not occur solely through lower-bit quantization or faster GPU kernels. It may also happen in an operating-system-like weight-management layer: deciding which parameters should remain resident, which can be evicted, which will be needed next, and how to keep data movement from blocking computation.
Colibrì does not make a 744B model lightweight enough for a laptop. It accepts that the model remains heavy, then finds a way to move only the parts currently needed.
That distinction is precisely what makes it more than a simple hardware gimmick: it is an inference-systems experiment worth continuing to validate.
References
- Zhihu: Running a 744B GLM Model on a Home Computer with 25GB of Memory—Introduces Colibrì’s basic principles, hardware configuration, and hierarchical loading approach. The performance figures cited in this article mainly come from publicly available materials; actual performance will vary with the model version, quantization format, SSD, and cache state.