Anonymous Jade Rabbit Tops Both OpenRouter Rankings
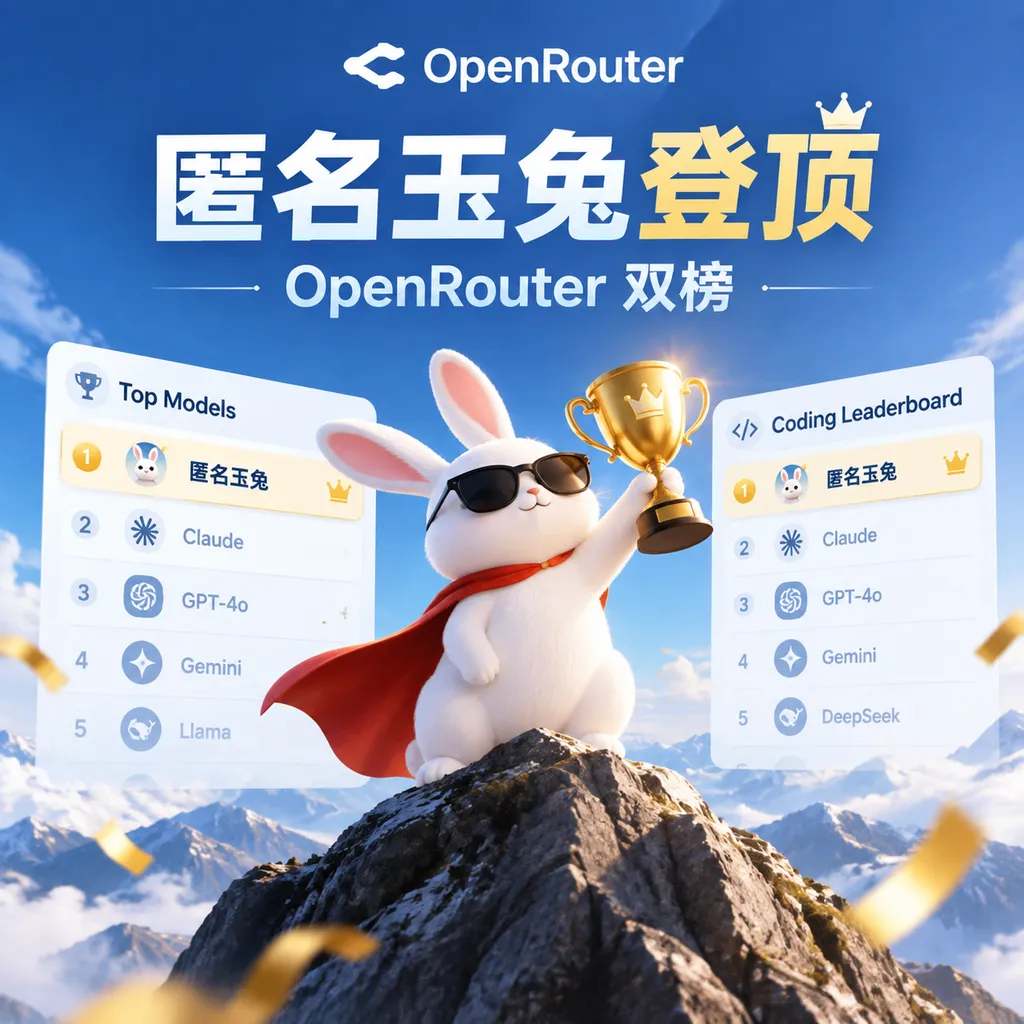
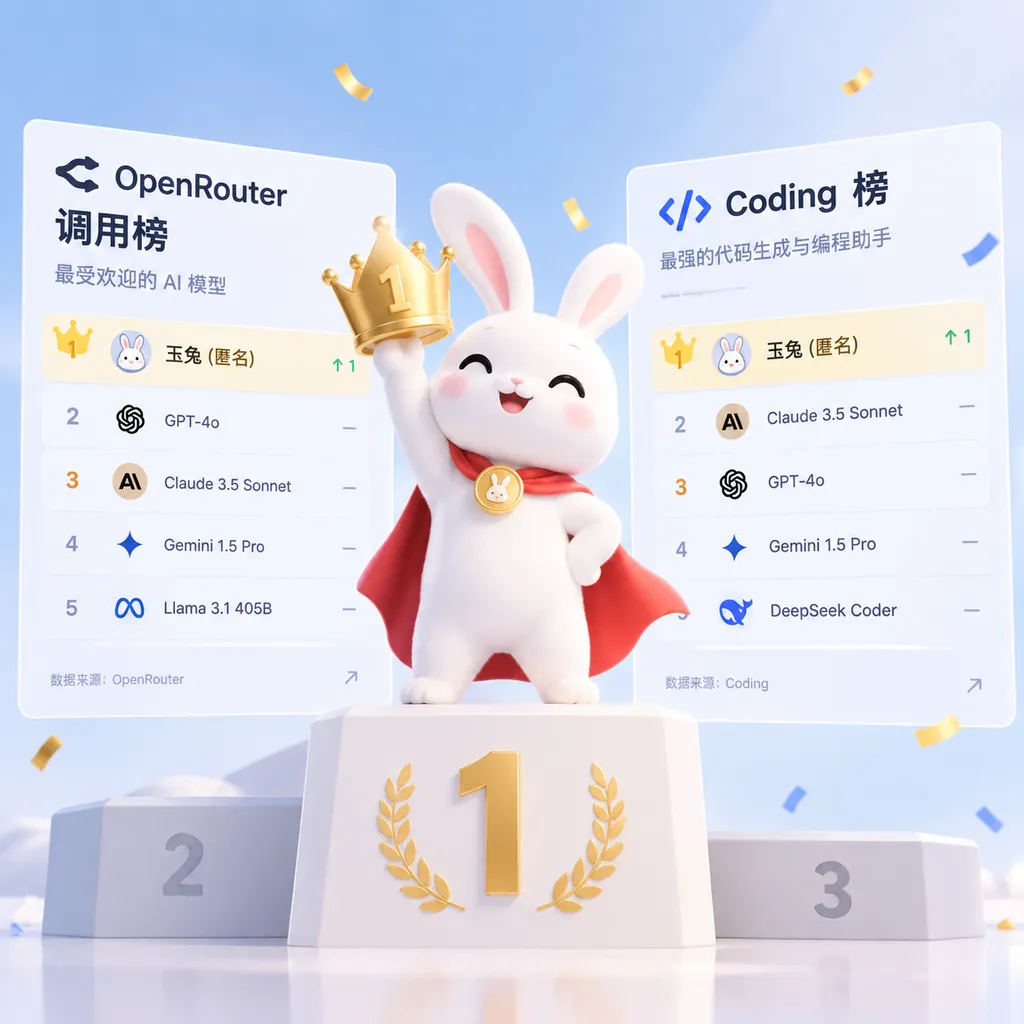
During the Mid-Autumn Festival holiday, the anonymous “Jade Rabbit” model surged to the top of OpenRouter’s daily usage rankings and simultaneously claimed the number-one spot on the Coding leaderboard. Developers’ hands-on testing showed that it is highly competitive in code generation, repository-level modifications, and tool use, but its model identity, stability, and long-term availability still need to be verified.
Anonymous “Jade Rabbit” Tops Both OpenRouter Rankings as Developers Line Up to Test It
A model with no public brand, no official launch event, and not even a clearly identified developer is attracting an unusual amount of attention on OpenRouter.
During the Mid-Autumn Festival holiday, the anonymous model “Jade Rabbit” climbed to first place on OpenRouter’s daily call-volume ranking while also topping both Coding-related rankings. Its popularity did not come from a major tech company announcing a new model. Instead, developers discovered through real-world programming tasks that the model’s speed, code-editing capabilities, and interactive experience may already be approaching the first tier of mainstream closed-source models.
What makes this worth watching is not simply the emergence of another ranking champion. More importantly, Jade Rabbit’s appearance once again shows that model competition is shifting from “who makes the biggest splash at launch events” to “who can be called continuously by developers in real workflows.”
Of course, an anonymous model topping a call-volume ranking cannot be directly equated with outperforming GPT, Claude, or Gemini in overall capabilities. OpenRouter’s call-volume rankings primarily reflect usage and distribution efficiency, rather than capability evaluations under strictly controlled variables. But when an unknown model ranks highly in both total usage and Coding scenarios, it demonstrates at least one thing: developers are willing to entrust it with real tasks, rather than merely trying it out with a couple of prompts in a chat window.
Why Did It Suddenly Become Popular?
Based on the information currently available, Jade Rabbit’s surge is mainly driven by three factors: speed, price expectations, and performance in coding scenarios.
The first is response speed. For coding assistants, speed is not merely an experience metric; it directly changes how they are used. If a model takes ten seconds or more to respond, developers will generally call it only when they encounter a complex problem. If it can quickly return a usable result, call frequency increases significantly. Tasks such as completing a function, explaining an error, modifying a configuration file, and generating test cases are all better suited to fast models.
One prominent impression from developers testing Jade Rabbit is that it is “fast.” This does not only mean a short time to first token; it also means that the time from understanding a request to providing a complete modification plan is relatively short. For Coding Agents, the latter is more important: a model that rapidly outputs an unfinished result will still leave developers spending time on rework. A model that can quickly complete analysis, editing, and verification has a real chance of reducing workload.
The second factor is the barrier to usage. Anonymous models typically lack a brand premium, and platforms can more easily present them to developers as cost-effective options. For requests running in CI, code review, batch refactoring, and automation scripts, differences in per-unit cost are quickly magnified. Even if a model is only slightly cheaper per response, when used millions of times a day in a development workflow, that difference can be enough to change users’ default choice.
The third is that it has hit the scenario most likely to generate word of mouth right now: writing code.
Differences between general-purpose chat models often require extended use to become apparent. Coding models, by contrast, can be tested quickly by developers against a concrete set of tasks. Can it understand an unfamiliar repository? Can it accurately locate a bug? Can it modify only the necessary files? Can it follow the existing project style? Can it continue fixing issues after a test fails? These questions can receive relatively clear answers within half an hour.
Jade Rabbit has evidently given many developers enough positive feedback to make it “worth testing further” on these tasks.
First Place on the Coding Ranking Does Not Mean It Only Completes Code
When discussing Coding models, it is easy to interpret “can write code” as “can generate a piece of text that looks like code.” But once a model enters an engineering environment, code generation is only the most superficial layer of capability.
A usable coding model must handle at least the following types of work:
- Requirements decomposition: Break natural-language requirements into a modification plan covering files, functions, interfaces, and tests.
- Repository understanding: Identify the frameworks, directory conventions, dependency versions, and existing abstractions used by the project, avoiding the introduction of an entirely new style out of nowhere.
- Targeted modifications: Change only the necessary code and avoid disrupting existing behavior as much as possible.
- Error diagnosis: Distinguish between compilation errors, type errors, runtime exceptions, and business-logic errors.
- Tool collaboration: Continue iterating based on terminal output, test results, and code diffs, rather than generating everything from scratch each time.
- Result verification: Know which changes require additional tests and which conclusions must be confirmed through actual execution.
Based on developers’ testing feedback, the reason Jade Rabbit has attracted attention is not simply that it writes attractive code snippets, but that it delivers relatively strong overall completion across multi-round Coding tasks. Put simply, it is more like an assistant capable of participating in an engineering workflow than a generator responsible only for “translating natural language into code.”
This is also the difference between Coding rankings and general model rankings. General rankings can create differentiation through questions involving knowledge, reasoning, or creative tasks. Coding scenarios expose a model’s context management, instruction following, restraint in making modifications, and error-recovery capabilities all at once. An impressive first response does not mean the model can stay on course after a test fails in the third round.
The Most Revealing Part of Testing Is How It Handles the “Dirty Work”
What truly separates coding models is often not writing a small function of a few dozen lines from scratch, but handling the work that nobody wants to do manually yet still has to be done.
For example, consider adding a small feature to a project that has been running for years. The requirement itself may consist of only a few sentences, but implementation requires first locating the routes, then finding the service layer, confirming the data structures, and finally adding frontend state and tests. If a model looks only at the current file, it can easily write code at the wrong layer. If it first scans the project structure and then modifies the code along the existing call chain, its success rate will be much higher.
Another example is fixing an intermittent error. The logs may contain only one vague line of exception information, while the real cause is hidden in an asynchronous workflow, cache invalidation, or an edge case. In this situation, the model needs to form hypotheses, inspect the relevant code, design a reproduction method, and then narrow down the answer based on test results. Whether it can complete this process is more representative of engineering ability than whether it can generate one correct piece of code.
Refactoring is another example. Developers generally do not want a model to “modernize the entire project” while it is at it. They want it to reduce duplication, fill in types, or split up an oversized module without changing external behavior. The more it changes, the greater the risk. An excellent Coding model should know when to exercise restraint.
The attention Jade Rabbit has received for these practical tasks suggests that it may have undergone targeted optimization for “understanding context and completing multi-step actions.” Whether this advantage comes from better training data, stronger reasoning strategies, context-window design, or engineering orchestration on the inference-service side cannot currently be determined from the limited public information.
An Anonymous Identity Is Both a Traffic Driver and a Source of Risk
The most distinctive aspect of Jade Rabbit is also its greatest risk: nobody knows who is behind it.
In the early stages of the model market, an anonymous release can create buzz, prevent brand expectations from influencing test results, and allow a model team to gather feedback quickly while its product is still immature. For developers, anonymous models also have a practical advantage: they can evaluate capabilities first and discuss the brand later, without first accepting a vendor’s narrative.
But production environments care about more than capabilities.
The first issue is stability. A model that rapidly climbs the call-volume rankings may have received prominent platform exposure, or it may be undergoing concentrated testing by a particular developer community. Whether it can maintain its latency, output quality, and API stability for a week, a month, or longer is what determines whether it is suitable for integration into real businesses.
The second is version consistency. If an anonymous model has no clear version numbers, changelogs, or deprecation policies, developers will have difficulty determining whether a change in output comes from a model upgrade, an adjustment to the system prompt, or a change in inference parameters. This uncertainty is particularly troublesome for code generation. A test that passes today may fail again tomorrow because the model’s behavior has changed.
The third is data and compliance. Code may contain business logic, internal interfaces, and undisclosed key configurations. When integrating an unknown model, developers should at minimum confirm whether requests are used for training, how long data is retained, in which regions the service is deployed, and whether the platform provides enterprise-grade isolation. Ranking position cannot replace this information.
The fourth is accountability when failures occur. When using mature services such as GPT, Claude, or Gemini, developers can at least find a clear service-status page, developer documentation, and support channels. If an anonymous model experiences widespread output anomalies or a service outage, end users may have difficulty determining responsibility or migrating quickly.
Therefore, Jade Rabbit is suitable as a new option worth testing, but it should not directly become a core production dependency while information about it remains opaque.
What Does This Rise Mean for OpenRouter?
Jade Rabbit’s surge also reflects the changing value of aggregator platforms such as OpenRouter.
In the past, the primary value of model aggregation platforms was providing a unified interface, allowing developers to switch between different models using the same OpenAI-compatible format. Today, these platforms also serve as channels for model distribution, discovery, and market validation. If an anonymous model had to face all developers directly, it would struggle to earn trust quickly. But when it appears in a unified model directory, call-volume ranking, and Coding ranking, developers gain a low-cost entry point for trying it.
This will accelerate the model market’s “trial-and-error cycle.” Model teams no longer necessarily need to build a strong brand before acquiring users. They can first exchange speed, price, or performance on specific tasks for usage, and then build a reputation in return. For platforms, more models mean more choices for users. For developers, lower switching costs make it easier to test new models.
But aggregation platforms also face a question: what exactly are the rankings rewarding?
If a ranking sorts only by call volume, it is closer to a traffic ranking than a capability ranking. Platform exposure, default ordering, price subsidies, rate-limiting policies, and integration with a popular client can all affect the results. A model may have high call volume because it is sufficiently capable, but it may also be because it is sufficiently cheap or has been selected by default for a large number of automated tasks.
A more ideal approach would present call volume, unique users, repeat-call rate, task completion rate, latency, failure rate, and performance across different scenarios separately. Only then could developers determine whether a model is merely “being tried” or actually “being retained.”
From this perspective, Jade Rabbit’s rise looks more like a market signal than a final verdict. It proves that developers are willing to give an anonymous model a chance, but it has not yet proven that the model has become stable engineering infrastructure.
Where Are Its Opportunities Compared with Mainstream Models?
Jade Rabbit’s real opportunity may not be to comprehensively defeat every mainstream model, but to find a sufficiently clear position.
Mature closed-source models still have advantages in complex architecture design, long-chain reasoning, cross-language engineering, and high-risk production code through their brands, toolchains, and long-term iteration. Their context capabilities, ecosystem integration, enterprise support, and security mechanisms are generally not things a new model can make up for with a few impressive rounds of testing.
But Jade Rabbit may have greater opportunities in high-frequency, low-latency development tasks with relatively clear boundaries:
- Fast code completion and localized code modifications;
- Generating repair suggestions based on error messages;
- Automatically adding unit tests and type definitions;
- Batch processing formatting, naming, and simple refactoring;
- Generating scripts and interface wrappers for internal tools;
- Serving as a low-cost default model for Coding Agents;
- Handling first-round analysis in complex tasks before handing them to a more capable model for review.
This is a highly practical division of labor. Development teams do not necessarily need to send every request to the most capable and most expensive model. A more common architecture is for an inexpensive, fast model to handle most routine tasks, while complex problems are escalated to a high-capability model. As long as Jade Rabbit can improve the success rate and speed of routine tasks, it may become an important part of this type of routing system.
How Should Developers Test It Now?
Simply opening a chat window and asking a few algorithm questions makes it difficult to determine whether Jade Rabbit is genuinely suitable for engineering use. More effective testing should be closely aligned with your own codebase and workflow.
You can start with the following types of tasks:
- Choose a real but low-risk repository and have the model first explain the project structure and key dependencies. Observe whether it can establish the correct context.
- Provide a small feature requirement and ask it to list a modification plan first, then make the code changes and add tests.
- Provide a reproducible bug and check whether it can continue iterating based on logs and test results.
- Ask it to perform a localized refactor, focusing on whether the diff is restrained and whether it unintentionally changes unrelated files.
- Conduct multiple rounds of follow-up questions to test whether it can remember earlier constraints instead of reinventing a solution each time.
- Repeat the same task at different times and record output differences, latency, and failure rate.
The evaluation metrics should also go beyond whether “the first version runs.” More practical metrics include first-pass success rate, the number of lines requiring manual modification, whether test coverage is appropriate, whether new dependencies are introduced, average response time, and the model’s success rate when repairing failures.
Pay particular attention to code-review costs. If a model generates large amounts of seemingly complete code that in practice requires line-by-line manual inspection every time, it is saving only keyboard input, not genuine engineering time.
Conclusion: Watch This Dark Horse First, Rather Than Crowning It Too Soon
The anonymous “Jade Rabbit” climbing to first place on OpenRouter’s call-volume ranking and both Coding rankings during the Mid-Autumn Festival holiday is indeed a noteworthy signal in the recent model market. It shows that developers are accepting new models increasingly quickly, and that Coding has become the primary battleground for testing a model’s real value.
But there is still a gap between being a ranking champion and being a production-grade model, encompassing stability, explainable version management, data governance, service guarantees, and long-term reputation. The most reasonable current positioning for Jade Rabbit is as a dark horse worth adding to a test suite immediately, not as a final answer ready to replace mainstream models.
For developers, the most valuable action is not repeatedly guessing which company built it, but putting it into real tasks and comparing it: use the same repository, the same test set, and the same constraints, and run it against the current default model. What ultimately determines whether it stays will not be a single ranking victory, but whether it can reliably reduce rework across dozens of consecutive tasks.
If Jade Rabbit later discloses its model identity, pricing, context specifications, and versioning strategy, the significance of this rise will become clearer. If it was merely a short-term traffic event, interest in the rankings will soon fade. If it can stabilize its current speed and Coding performance, it may become one of the most representative examples of a new model’s growth on an aggregation platform such as OpenRouter.
Sources
- IT Home: Used to supplement industry background information on OpenRouter model usage popularity, model usage patterns, and related topics. Since the original source of the “Jade Rabbit” report is outside the specified list of citable domains, the core information in this article regarding Jade Rabbit’s rankings and developer testing was compiled from the reference materials provided in the prompt.