Kaiming He’s Team Challenges ARC with Vision Models
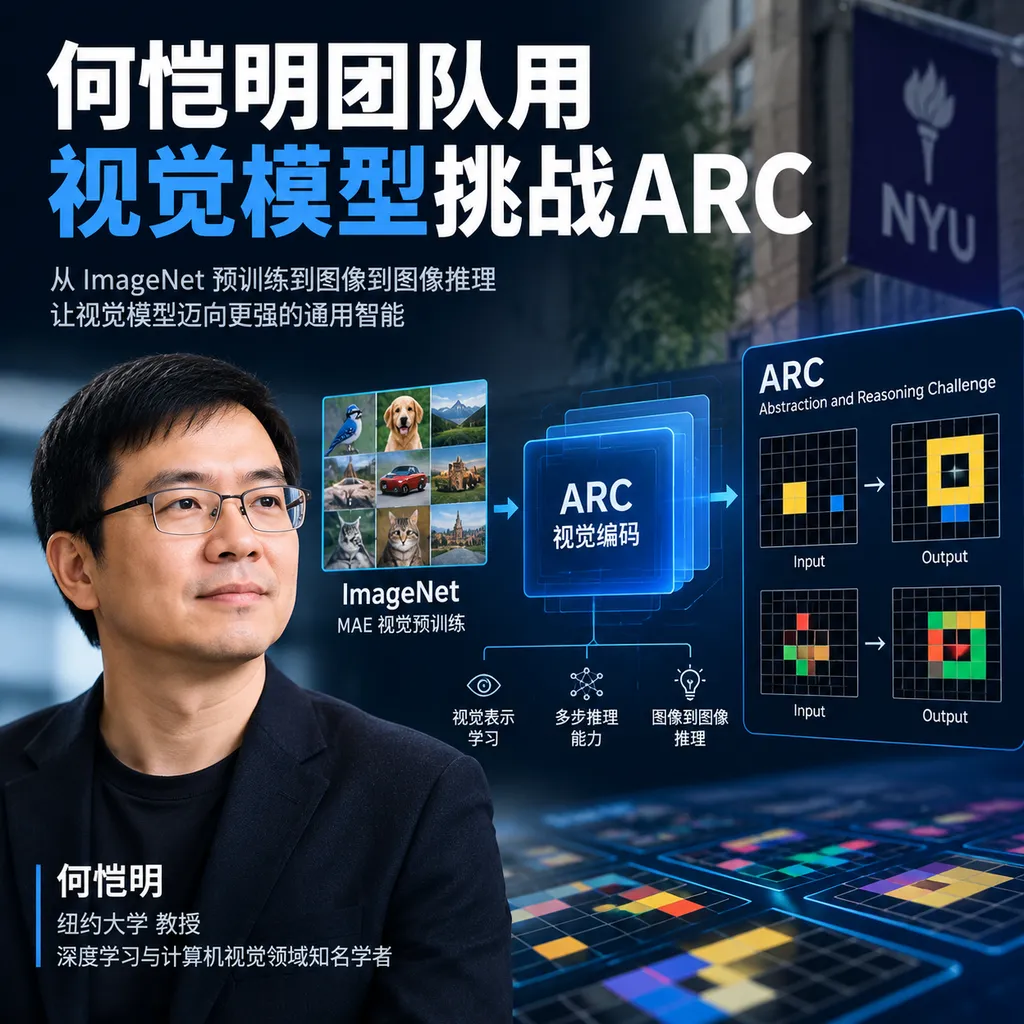
Kaiming He’s team proposes NAT-ARC, transferring MAE visual pretraining on ImageNet to the abstract reasoning task ARC. The results show that models do not need to convert colored grids into text and can approach specialized large-model systems through a purely visual pipeline.
Kaiming He’s Team Challenges ARC with Vision Models
Kaiming He’s team recently proposed NAT-ARC, a method for solving ARC abstract reasoning tasks directly with vision models—without relying on language models or converting colored grids into text.
What deserves the most attention is not how many percentage points it has improved, but the validation of something that has long been underestimated: the shapes, spatial relationships, and structural changes that vision models learn from natural images may be transferable to completely abstract colored grids. In other words, a model may not need to first learn how to “read the question”; it may be able to learn how to “see the pattern” directly.
However, “watching cat videos is enough to learn ARC” is more of an eye-catching summary than a conclusion of the paper. NAT-ARC’s key pretraining source is MAE self-supervised training on ImageNet. The model sees natural images of cats, dogs, plants, vehicles, and so on; during the actual ARC training stage, it still uses ARC task data. It does not acquire reasoning ability out of nowhere from a few clips of cats alone, but it does show that general-purpose visual pretraining can bring benefits to abstract reasoning models similar to those provided by language-model pretraining.
Why Is ARC Difficult?
ARC stands for Abstraction and Reasoning Corpus. It was proposed in 2019 by François Chollet, the creator of Keras. Its task format is simple: both the input and output are colored two-dimensional grids. The model must observe several input-output examples, infer the hidden transformation rule, and then apply that rule to a new input.
A typical task may require the model to perform the following operations:
- Identify a connected region of a particular color in the grid;
- Determine whether a shape has been rotated, mirrored, or translated;
- Generate a new pattern based on the relative positions of objects;
- Recognize a repeated structure and copy it to a designated area;
- Ignore the background and rearrange or recolor only objects that meet certain conditions.
The grids are typically no larger than 30×30, use at most ten colors, and contain only two to five training examples. The difficulty lies in the fact that the rule may be different for every problem, while the amount of data is extremely small. A model cannot solve the tasks by memorizing problem types; it must perform one-shot induction from only a handful of examples.
This is also the fundamental difference between ARC and ordinary visual classification tasks. ImageNet asks the model to determine “what this is,” whereas ARC asks it to determine “why it changes this way.” The former primarily tests recognition, while the latter is closer to program induction, relational reasoning, and compositional generalization.
For humans, these tasks resemble children’s puzzle games. When people see several blocks move, duplicate, or change color, they can usually grasp the objects and rules quickly. For a model, however, the challenge is to perform object segmentation, relation modeling, rule abstraction, and precise execution simultaneously—and every task lacks a universal answer template.
The Prevailing Approach in the Past: Turn the Image into Text First
For a long time, the dominant approach to ARC involved large language models. The usual method was to encode grids as sequences of numbers, characters, or symbols—for example, using different numbers to represent different colors—then concatenate the input-output examples into a prompt and give it to a language model for reasoning.
This approach has a practical advantage: language models have already learned sequence patterns, conditional reasoning, and rule execution from massive amounts of text and code. For them, an ARC grid can be treated as a special kind of “program input and output,” turning the problem from a visual task into symbolic manipulation.
But this approach also introduces an obvious intermediate layer. The model does not see the original grid; it sees a human-designed textual representation. The spatial relationships, local shapes, and object boundaries in the grid must first be encoded before they can enter the language model. Once the encoding method changes, the model’s performance may also be affected.
NAT-ARC takes a different path: no translation, no description, and no outsourcing to a language model. It treats the grid directly as an image to be processed.
What Does NAT-ARC Do?
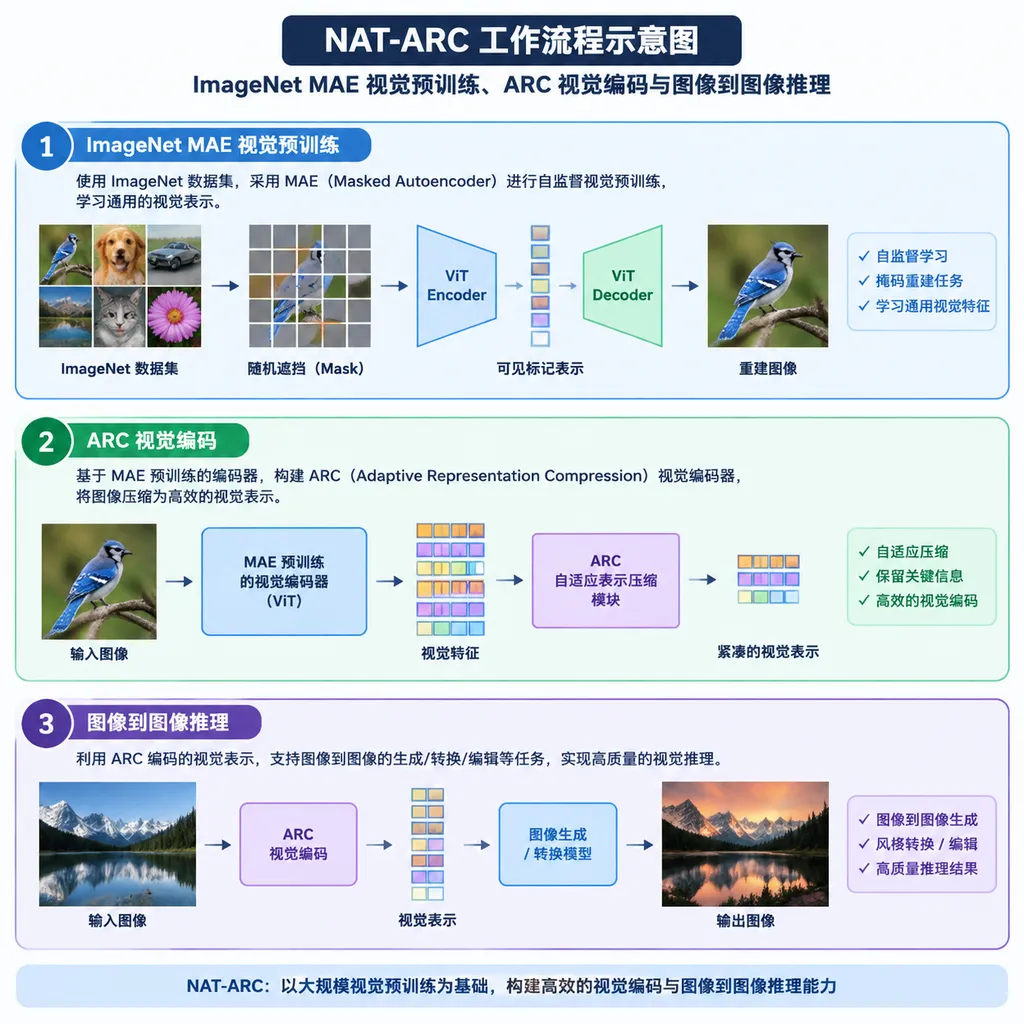
The core idea behind NAT-ARC is to redefine ARC as a visually conditioned generation problem. Given several pairs of input and output grids, the model must learn the transformation rule from input images to output images. This idea follows the direction of previous visual ARC work such as VARC, while further adding a visual pretraining component.
Its general process can be summarized in three steps:
- Perform visual pretraining on natural images to obtain an encoder with general structural awareness;
- Use the pretrained encoder for visual representations of ARC grids;
- Train on the task so that the model learns the transformation between input and output grids.
Conceptually, it can be written as:
ImageNet images
      |
      v
MAE self-supervised pretraining
      |
      v
visual encoder initialization
      |
      v
ARC input/output grids
      |
      v
visual transformation model
      |
      v
predicted output grid
The method uses MAE, or Masked Autoencoder. During training, the model sees an image with most of its regions masked and must reconstruct the complete image from the remaining content. It does not rely on human-provided labels; the training objective is to reconstruct the masked pixels or image content.
MAE may appear to be performing image completion, but in the process the model gradually develops representations of object boundaries, local structures, spatial layouts, and overall shapes. MAE, proposed by Kaiming He during his time at Meta AI, is one of the most influential methods in visual self-supervised learning.
NAT-ARC uses MAE encoder weights trained on ImageNet to initialize its visual encoder, while the decoder starts training from a random state. This choice has an important implication: what the model brings to ARC is not the answers to particular tasks, but structural priors formed through exposure to the natural visual world.
Why Might “Watching Cat Videos” Work?
Natural images and ARC grids appear to have almost nothing in common. Cats, dogs, cars, and plants in ImageNet are real objects composed of continuous pixels, whereas the blocks in ARC are abstract symbols made up of discrete colors. Why can a model transfer what it learned from the former to the latter?
The answer may not be that the model recognizes “cats,” but that it has learned more fundamental ways of organizing visual information.
For example, in natural images, the model needs to distinguish foreground from background, identify object edges, determine whether local regions belong to the same whole, and understand the spatial relationships between objects. Although ARC contains no real-world objects, it likewise has objects, backgrounds, boundaries, connected regions, repeated patterns, and relative positions.
This is similar to how a person learning geometry does not necessarily need to have seen a particular exercise before. As long as they understand shapes, distances, symmetry, and positional relationships, they can continue reasoning when presented with a different set of figures. What ImageNet pretraining provides may be precisely this kind of general visual bias, rather than knowledge of any specific category.
Of course, this transfer also has limits. Natural images are continuous and rich in noise, whereas ARC grids are discrete and highly regular. Visual pretraining can help the model build representations, but it cannot replace rule induction from ARC itself. The model still needs to learn from ARC tasks how to manipulate objects, copy structures, and perform transformations.
Therefore, the more accurate description is this: natural-image pretraining gives purely visual ARC models a better starting point; it does not allow a model to master ARC directly by looking only at natural images.
From Random Initialization to Visual Pretraining
Previous visual ARC models often began training from random initialization. VARC treated ARC as an image-to-image translation problem and achieved approximately 54% accuracy on the ARC benchmark with a vision model containing about 19 million parameters. Later, LoopViT introduced an iterative reasoning mechanism and reached approximately 65.8%; Loop-OWM further used a video-pretrained model for few-shot learning and reached approximately 68.5%.
The significance of these figures is that language models with billions of parameters are not the only way to solve ARC. A vision model with only tens of millions of parameters can also achieve comparable results on few-shot abstract tasks, provided that its architecture is appropriately designed.
However, the visual approach has long faced an obvious bottleneck: increasing model size does not automatically lead to improved capabilities. The reason is simple. Many models start with random weights, while ARC provides extremely little data. The model does not receive enough training signals to establish stable visual representations, let alone accumulate capabilities through large-scale pretraining in the same way language models do.
NAT-ARC’s main contribution lies in introducing pretraining into this process. The question it attempts to answer is not “Can vision models do ARC?” but rather “Can vision models, like language models, acquire transferable foundational abilities through pretraining?”
If the answer is yes, visual ARC may no longer be a one-off architecture competition. It could develop its own scaling path: better visual pretraining, larger or more diverse data, stronger task adaptation, and more effective test-time reasoning.
How Does It Compare with Large Language Models?
Judging from the results, NAT-ARC is considered the first purely visual approach to come close to the performance level of specialized LLM systems. This is a noteworthy signal, but it should not be interpreted as meaning that vision models have comprehensively defeated language models.
First, ARC’s scoring method is highly sensitive to precision. If there is even one critical error in the output grid, the entire task may be marked incorrect. Therefore, a model’s average accuracy cannot fully reveal whether it has understood the rule or merely formed effective guesses for certain patterns.
Second, language-model approaches often combine search, program generation, candidate-answer selection, and other mechanisms. They may not rely solely on a single forward pass; instead, they use the language model as a rule proposer and then improve the results through execution or verification. When comparing pure vision models with such systems, it is necessary to confirm whether the parameter scale, inference budget, data usage, and post-processing pipeline are comparable.
Third, the difficulty and task distributions of different versions of ARC-AGI, as well as ARC-1 and ARC-2, are not completely the same. A model achieving high accuracy on one particular data split does not necessarily possess broad abstract reasoning ability. More convincing evidence should include cross-task generalization, tests on unseen rules, different grid sizes, and robustness to perturbations and color permutations.
Therefore, NAT-ARC’s more important value is that it opens up a path, rather than providing a final answer. It shows that visual representations are not an inherent obstacle to ARC reasoning, and that language is not the only medium for abstract reasoning.
Implications for Model Research
This work offers at least three insights.
1. The Value of Pretraining May Emerge Before the Value of Model Scale
ARC contains very little data, so simply adding parameters is not practical. For few-shot tasks of this kind, initialization, inductive bias, and training objectives may matter more than parameter count. A small or medium-sized model with suitable pretrained representations may have a chance to outperform a larger model without prior knowledge.
2. The Boundary Between Vision and Language Is Less Solid Than Imagined
People often associate language models with “reasoning” and vision models with “perception.” But ARC shows that some reasoning abilities can in fact be achieved through visual representations. Concepts such as objects, positions, symmetry, copying, and transformation do not inherently belong to language.
This does not mean that language models have no value. Natural language remains well suited to expressing rules, explaining processes, and combining complex knowledge. A more likely trend is that different model approaches will learn from one another at the representation and reasoning levels, rather than one paradigm simply eliminating the other.
3. Abstract Reasoning Requires More Rigorous Evaluation
ARC is important because it is not easily contaminated by Internet training data and is not particularly amenable to being solved through memorization. But it is still not a complete test of general intelligence. A model may be good at grid transformations while being poor at causal reasoning in the real world, long-term planning, or open-ended problem solving.
Future evaluations should not look only at a single leaderboard number. They should also analyze whether the model has genuinely learned the rules, whether it can explain its errors, whether it can adapt to changes in colors and sizes, and whether it remains stable when facing entirely new tasks.
What Does This Mean for Developers?
In the short term, NAT-ARC will not directly change ordinary application development. It is not a general-purpose visual API that can be integrated immediately, nor is it a shortcut for converting ARC performance into product capabilities. For code generation, search, customer service, and multimodal applications, mature large language models remain more practical.
But it does offer practical lessons for model engineering:
- For specialized tasks with limited data, high-quality pretraining may be more important than blindly expanding fine-tuning data;
- If a task is fundamentally about spatial transformations, object relationships, or structural matching, a pure vision model may be more direct than “converting an image to text and then handing it to an LLM”;
- For discrete grids, game boards, flowcharts, and industrial defect detection, image-to-image modeling may not require a language intermediate layer;
- When evaluating models, recognition, rule induction, execution, and verification should be distinguished rather than collectively labeled as “reasoning.”
For practical systems, a more reasonable architecture may not be a choice between purely visual and purely linguistic approaches. Instead, a vision model could be responsible for reliably extracting structure, a language model could handle explanation, planning, and interaction, and an executable verifier could be used to check the final result. NAT-ARC demonstrates that a visual module can take on more reasoning work; it does not mean that all reasoning should be assigned to vision models.
Conclusion
The appeal of Kaiming He’s team’s research does not lie in the lighthearted “cat videos” headline, but in the key question it brings to the forefront: does abstract reasoning ultimately require language, or does it only require sufficiently good structural representations?
NAT-ARC’s answer is that, at least for tasks like ARC, the visual approach is fully qualified to compete. The shape and spatial priors provided by natural-image pretraining can transfer to object transformations in colored grids, while rule induction—previously thought to have to be handled by an LLM—can also be performed in part by a relatively small vision system.
This is not yet a victory declaration for vision models. ARC remains a highly controlled benchmark, and NAT-ARC does not prove that the model has acquired general abstract abilities in the human sense. But it does make the statement “vision models can only recognize; they cannot reason” increasingly untenable.
What is truly worth watching next is whether visual pretraining can continue to scale to more difficult ARC tasks, more complex compositional rules, and structured problems in the real world. If the answer is yes, the next round of model competition may not be only about whose language model is larger, but also about who can connect vision, symbols, and action more effectively.
References
- Zhihu: Kaiming He’s Team Releases Another Result: Vision Models Challenge ARC — An introduction to Kaiming He’s team’s visual ARC approach and related experimental background.
- Tencent Cloud Developer Community: An Interpretation of the VARC Visual ARC Method — An introduction to VARC’s approach of converting ARC into an image-to-image task and its results.
- Juejin: Solving ARC with Purely Visual Methods — A review of the development and technical approaches of using vision models for ARC tasks.