Mistral announces: New model launching today, with cybersecurity capabilities surpassing Chinese competitors
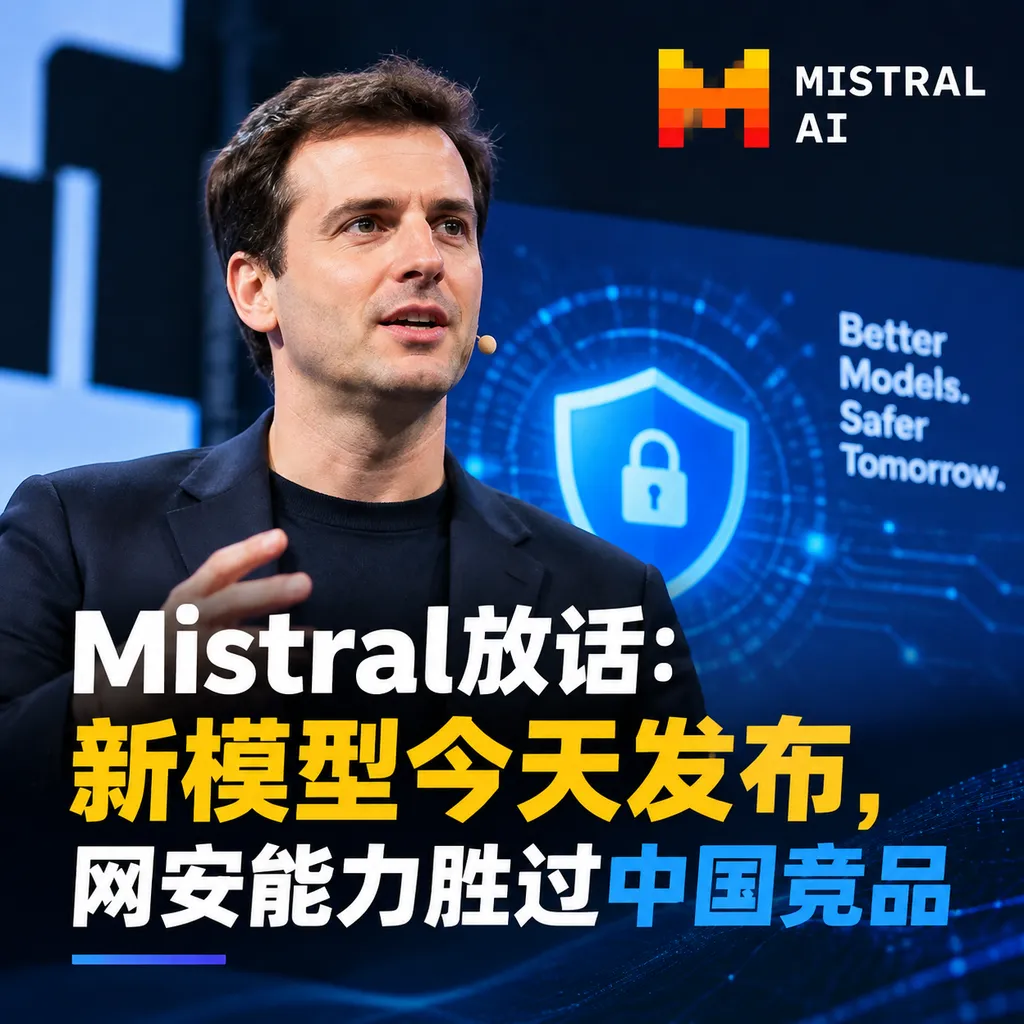
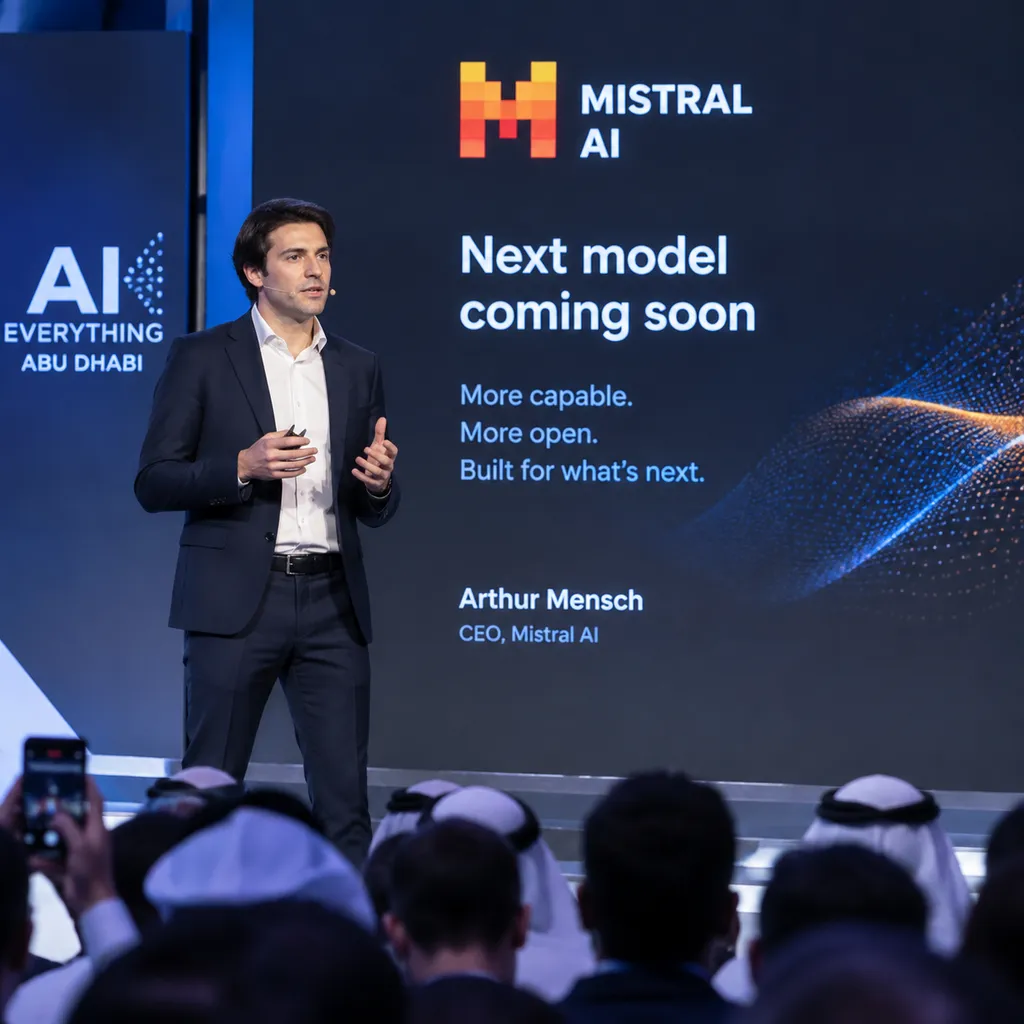
Mistral AI CEO Arthur Mensch publicly previewed in Abu Dhabi that the company would release a new model today, claiming that it outperforms Chinese models in areas such as cybersecurity. However, until the specific model, comparison targets, and test results are disclosed, this looks more like a public rallying call for Europe's AI competitiveness.
Mistral Announces a New Model Today, Putting “Cybersecurity Capabilities” Front and Center
French artificial intelligence company Mistral AI is building anticipation for the release of a new model today.
According to a report by Reuters cited by IT Home, Mistral AI CEO Arthur Mensch said on October 6 local time at the Ai Everything conference in Abu Dhabi, United Arab Emirates, that the company would release a new artificial intelligence model that day. He also offered a notably aggressive assessment: in certain capabilities, including cybersecurity, the model is “actually better than Chinese models.”
Mensch did not disclose the model’s name, nor did he specify the comparison targets, test versions, or exact scores. His remarks sounded more like market positioning than a complete technical launch: Europe is not incapable of competing in frontier models, and users are actively seeking alternatives to suppliers from the United States and China.
The significance of the statement is not merely that “a new model is going live today.” It is that Mistral has chosen a highly sensitive area that is also well suited to differentiation: cybersecurity.
Why Cybersecurity
The cybersecurity capabilities of large models are no longer simply a question of whether they can “write a Python script.” In the eyes of developers and security teams, they include at least several layers of capability:
- Whether the model can discover vulnerabilities in code, including privilege bypasses, injection flaws, memory-safety issues, and supply-chain risks;
- Whether it can understand real attack chains rather than merely listing security terminology based on keywords;
- Whether it can assist with vulnerability reproduction, patch development, and security audits;
- Whether it can analyze logs, alerts, and infrastructure configurations within the scope of legitimate authorization;
- Whether it can identify malicious requests and avoid turning the model itself into an automated attack tool.
Therefore, “stronger cybersecurity capabilities” is a very broad conclusion. It could mean more accurate vulnerability detection, or better performance in secure code generation, red-team simulation, malicious-sample analysis, or defensive recommendations. Results across different tasks cannot be treated as interchangeable.
For example, a model that scores highly at finding SQL injection vulnerabilities in web applications is not necessarily capable of accurately assessing identity and permission chains in a cloud environment. A model may generate remediation advice that looks professional, but that does not mean the advice has been validated on a real system. In security, it is particularly easy to end up with “code that runs, but a fix that does not work.”
Therefore, if Mistral wants to turn its publicity into a credible technical conclusion, it will need to disclose at least the test sets, evaluation methodology, permitted scope of tool calls, and the models used for comparison. Otherwise, “better than Chinese models” remains a boundaryless claim.
Which “Chinese Competitors” Matters to the Claim’s Weight
Mensch did not name any specific Chinese models, and that is significant.
Over the past year, models such as DeepSeek, Kimi, and Qwen have continued to expand their influence in reasoning, coding, long-context processing, and the open-weight ecosystem. Together, they have changed the competitive dynamics of the large-model market: models are no longer compared only by parameter count and benchmark scores, but also by inference costs, deployment barriers, openness, and developer ecosystems.
If Mistral was comparing itself with general-purpose conversational models available in the Chinese market, its advantage in cybersecurity could come from the composition of its training data, coverage of English-language security materials, tool-calling capabilities, or specialized post-training processes. If it was comparing itself with flagship models that already possess strong coding and reasoning capabilities, the conclusion would require more rigorous support from third-party evaluations.
That is why a single sentence at a launch event is not enough to determine whether Mistral has genuinely achieved a technological breakthrough. Evaluating cybersecurity models is far more complex than evaluating ordinary knowledge question answering. A model must solve the problem while maintaining boundaries between authorization, risk, and factual accuracy.
For developers, what really matters is not a claim about “beating” a particular model, but the following metrics:
- Vulnerability detection and false-positive rates: Finding more issues does not mean finding them accurately. Security teams most fear an avalanche of alerts that buries genuinely critical problems.
- End-to-end capability from analysis to remediation: Can the model explain the cause of a vulnerability and submit a tested patch, rather than merely outputting code that appears reasonable?
- Tool-use capabilities: Does it support security scanners, code repositories, terminals, and logging systems, and can it maintain context across multi-step tasks?
- Generalization to unknown problems: When faced with vulnerability types absent from its training data, can the model still form effective attack and defense hypotheses?
- Security boundaries: Can the model distinguish authorized testing from real attack requests, and does it provide auditable refusal and access-control mechanisms?
If Mistral only publishes scores on common coding benchmarks, the promotional value of its cybersecurity claims will clearly exceed their practical reference value.
Mistral Needs More Than a Stronger Model
Mistral is one of Europe’s most closely watched artificial intelligence companies. Its position is distinctive: it must compete with American companies such as OpenAI, Google, and Anthropic, while also facing pressure from Chinese models such as DeepSeek and Qwen in open weights and cost efficiency.
Demand for local models in the European market is not simply a matter of “who has the highest benchmark score.” Financial, healthcare, government, and defense customers are generally more concerned with whether data can remain local, whether the model can be audited, whether the supplier is subject to regional laws, and whether supply can remain stable as international relations change.
This gives Mistral a realistic commercial opportunity. Open-weight or more easily locally deployable models can help enterprises reduce their dependence on a single cloud provider. For security teams handling source code, vulnerability reports, customer data, and internal logs, running models locally or in private environments is not an abstract concept of sovereignty. It is a matter of data flows, compliance responsibilities, and incident traceability.
But this path is also difficult. The advantages of open-weight models are deployability, fine-tuning, and auditability; the tradeoff is that model capabilities, inference costs, update speed, and security maintenance responsibilities may all shift to the user. Downloading a model does not immediately give an enterprise a reliable security analysis system. It must still solve problems involving inference infrastructure, permission isolation, prompt injection, log retention, and output validation.
From this perspective, whether Mistral’s new model released today can genuinely attract developers will depend on whether it answers three questions at the same time: How capable is the model, what will deployment cost, and can enterprises integrate it into their existing workflows?
The Release May Continue an “Efficiency First” Strategy
Mistral’s product strategy has not been focused exclusively on maximizing parameter count. Instead, it has emphasized a strong balance between performance and deployment efficiency. Its previously released models have covered multiple sizes, from flagship cloud models to smaller local models, giving the company a recognizable position among European enterprises and developer communities.
If today’s new model continues along this path, developers may focus on several changes:
- Whether it adopts a mixture-of-experts architecture to reduce the number of parameters actually activated for each request;
- Whether it offers a longer context window to support analysis of large code repositories and multiple security reports;
- Whether it strengthens function-calling and tool-orchestration capabilities to facilitate integration with scanners, terminals, and ticketing systems;
- Whether it offers open weights and an open license, and whether commercial use is permitted;
- Whether it provides quantized versions suitable for local deployment;
- Whether it achieves a better balance between code generation, code review, and reasoning tasks.
For security engineering teams, the price per million tokens is certainly important, but it is not the only cost. A cheap model that frequently generates false positives will consume engineers’ time on ineffective reviews. A highly capable model with limited context and tool-calling support will also struggle to fit into a real DevSecOps workflow.
The ideal security model is not one that “presses the attack button” on behalf of engineers. It should be able to read complex code, locate risks, provide verifiable remediation plans, and keep every step of its reasoning and tool use within an auditable process.
What This Means for Developers
Before the model’s specific details are announced, developers do not need to replace their existing technology stacks based on a single preview. A more sensible approach is to conduct small-scale tests around their own tasks once the model goes live.
Four types of scenarios can be tested first:
- Conduct a vulnerability audit on a real but sanitized service repository;
- Ask the model to analyze a set of historical alerts and observe its false-positive and false-negative rates;
- Ask the model to generate patches for vulnerabilities, then run existing tests and static checks;
- Under a fixed budget, compare the time and manual review costs required by different models to complete the same security task.
Data-leakage risks must also be controlled during testing. Source code, internal domains, credentials, vulnerability details, and customer logs should not be sent directly to unapproved public interfaces. Even if a model provider claims that it will not use the data for training, the decision should still take into account the organization’s logging policies, retention periods, and cross-border data-transfer requirements.
If Mistral provides an open-weight version, its value will be reflected more directly in its controllability: enterprises can run the model on their own infrastructure, fine-tune it using internal data, and restrict tool permissions through a gateway. But this also means that enterprises will be responsible for model updates, vulnerability fixes, and security-policy maintenance.
Competition for European Models Will Not End with a Slogan
Mistral’s decision to preview the release in Abu Dhabi and emphasize that Europe can provide an alternative technology supplier outside the United States and China carries clear industrial and geopolitical significance.
Europe wants its own frontier-model companies for reasons that go beyond competing for leaderboard rankings. It needs to retain choice in critical infrastructure, data governance, and government procurement, while also avoiding the risk of having the entire AI application layer locked into a small number of American platforms.
But the “third pole” narrative must ultimately return to the product. For developers, where a model comes from certainly matters, but what matters more is whether it is smart enough, affordable enough, stable enough, and usable under clear licensing and deployment conditions.
Mistral’s release today could represent a genuine model upgrade, or it could primarily be a brand statement aimed at the European market. Until the specific model, weights, pricing, and evaluation results are published, the most prudent conclusion is that it is worth watching, but it is still too early to declare that European models have overtaken their Chinese competitors.
If the new model truly performs exceptionally well on cybersecurity tasks, it could open a more valuable vertical market for Mistral than general-purpose chat. If it represents only a conventional capability improvement, it will still face cost and ecosystem pressure from models such as DeepSeek, Qwen, and Kimi.
The answer will come with today’s official release and subsequent real-world testing. For developers already using OpenAI-compatible APIs, it will be worth watching whether OpenAI Hub integrates the model, as well as its model name, context limits, pricing, and tool-calling support. Until those details are clear, however, any conclusion that it is “ahead across the board” would be premature.
Sources
- IT Home: Mistral AI previews a new model today that can outperform Chinese competitors in areas including cybersecurity — The primary source for this article’s information about the release preview, Arthur Mensch’s remarks, and his statements.
- IT Home: Mistral to launch its first reasoning model, Magistral — Provides background on Mistral’s recent model strategy and the development of its reasoning capabilities.
- ifanr: Europe’s version of DeepSeek releases a new model and takes aim at Chinese AI — Provides additional market context on Mistral’s existing models and competition with Chinese open-source models. This link is included for background reading only and is not a direct source for the current preview.