EmbeddingGemma 2 Comes to Mobile
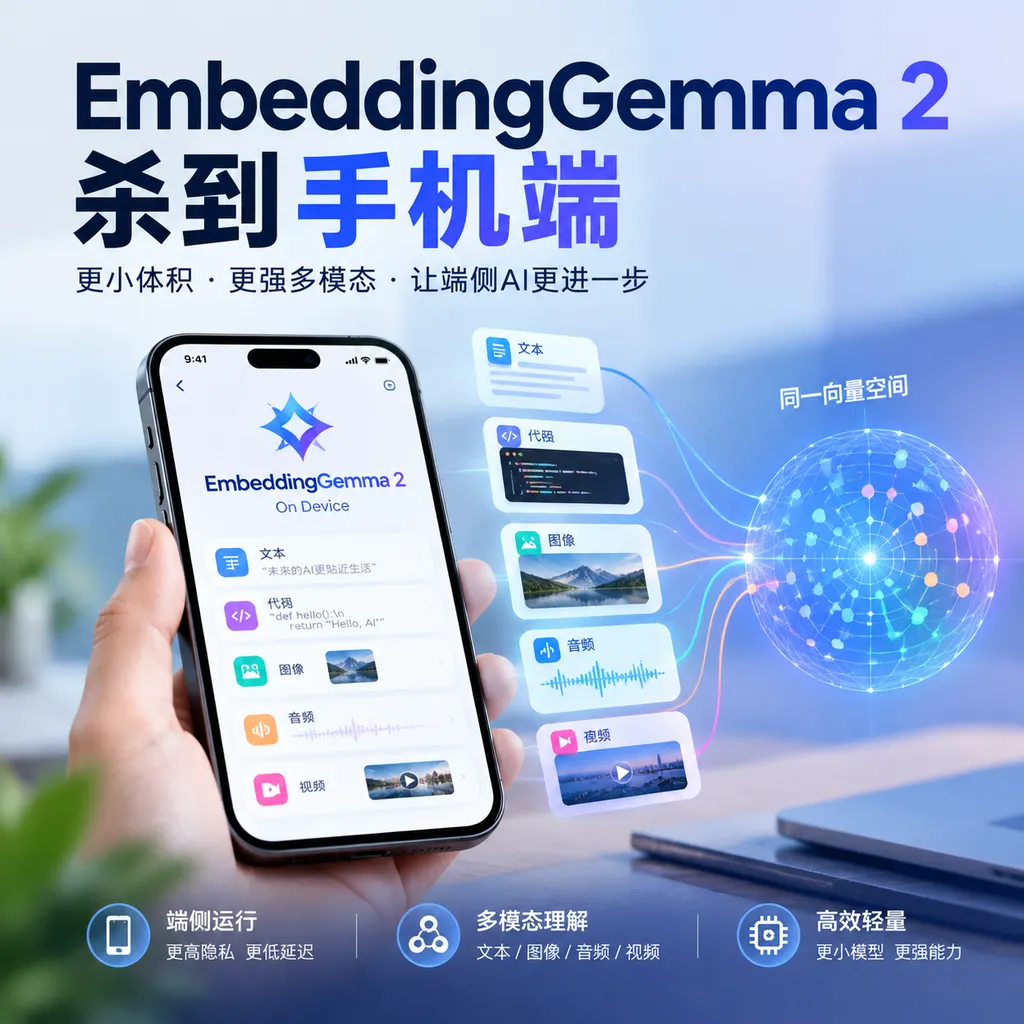
Google has released EmbeddingGemma 2, a 740-million-parameter open-source multimodal embedding model that supports unified retrieval across text, code, images, video, and audio. After quantization, the text-only version requires only about 191 MB of memory, while the full multimodal version requires approximately 567 MB, enabling offline RAG on mobile devices.
EmbeddingGemma 2 Hits Phones: Multimodal Embeddings Use Just 191 MB of Memory
On October 7, Google released EmbeddingGemma 2, an open-source multimodal embedding model designed for on-device deployment.
It can map text, code, images, video, and audio into the same vector space. After quantization, the text-only weights require approximately 191 MB of active memory when running on a Google Pixel 11 Pro, while loading the complete multimodal model requires about 567 MB.
This is not another “small model” trying to chat on a phone. EmbeddingGemma 2 has a more fundamental purpose, and one that is closer to the infrastructure developers actually need: enabling local files, photos, recordings, videos, and codebases to be indexed, retrieved, and matched through a unified system, without first uploading the data to the cloud.
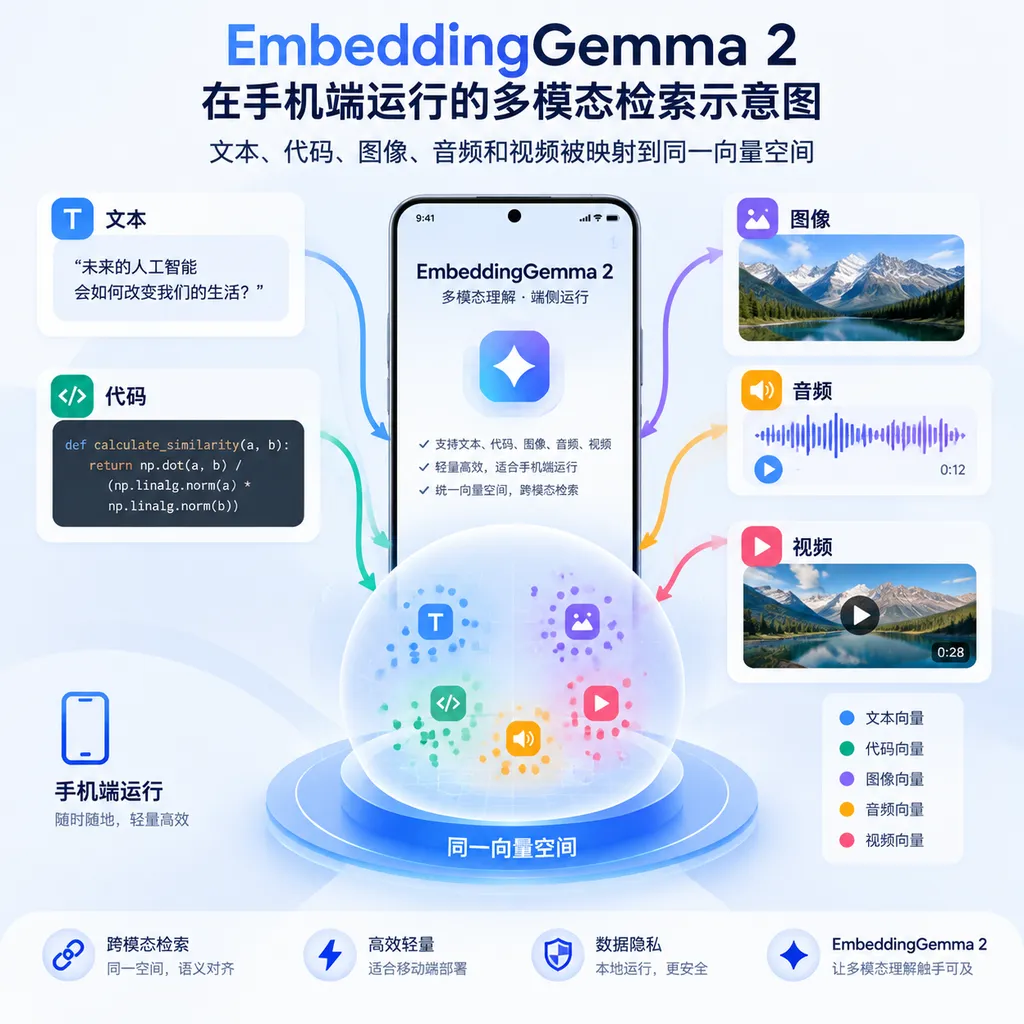
Google Takes Embedding Models from Text to Multimodality
The job of an embedding model is not complicated: it converts a piece of text, an image, or an audio clip into a sequence of numbers. Semantically similar content is also closer together in vector space. Search, recommendation, classification, clustering, and RAG all rely on this ability to “turn content into a computable representation.”
The problem in the past was that different modalities often required different models and indexing paths.
Text search typically requires documents to be split into chunks before generating text embeddings; image search relies on vision encoders; and audio often needs to be transcribed into text first or processed with a specialized audio feature model. Developers ultimately end up with several disconnected processing pipelines rather than one unified system.
EmbeddingGemma 2 attempts to unify this process. Users can use a text query to match a photo, an audio recording, or a video segment, and can also place voice memos, meeting photos, and code snippets into the same retrieval system. For on-device applications, this means that many tasks that previously required “upload first, analyze next, retrieve afterward” may now be completed directly on the device.
Google’s first-generation EmbeddingGemma, released last year, was primarily designed for multilingual text embeddings. Google says the model has been downloaded more than 20 million times, with applications including on-device search tools and privacy-first RAG pipelines. The biggest change in the second generation is not simply a larger parameter count, but an expansion of the model’s input range to include code, vision, and audio.
740 Million Parameters, but Not All Modules Need to Load Together
EmbeddingGemma 2 has a total of 740 million parameters. It is built on the Gemma 4 architecture and technology derived from the same lineage as Gemini embedding models, and is released under the Apache 2.0 license.
However, 740 million parameters does not mean every task has to bear the cost of the full model. Google uses a modular design:
- Text-only tasks use approximately 270 million parameters;
- The vision encoder contains approximately 170 million parameters;
- The audio encoder contains approximately 300 million parameters;
- Different encoders are combined only when full multimodal capabilities are required.
This design is particularly important for mobile devices. A search function in a phone app may not need image and audio capabilities, while a coding assistant may not need to load the vision module. If an application only performs local document search, developers can load just the text component; if they want semantic photo search, they can bring in the vision encoder as needed.
On a model-serving server, a difference of a few hundred megabytes may amount to little more than a deployment configuration. On a phone, it directly affects package size, startup speed, background residency, and battery consumption. The point of modularity is to ensure that developers do not pay for capabilities they do not use.
According to Google, after quantization and when running on a Pixel 11 Pro, the text weights of EmbeddingGemma 2 consume approximately 191 MB of active memory, while the complete multimodal model consumes about 567 MB. This is not the “model file size,” nor is it equivalent to the application’s total memory usage. At runtime, the overhead of the inference framework, input buffers, vector database, and application code must also be added.
Even so, this is already a practically meaningful footprint for an on-device embedding model. In particular, the 191 MB required for text retrieval gives it a chance to be deployed in note-taking apps, file managers, code editors, photo libraries, and personal knowledge bases, rather than remaining limited to high-end devices or demonstration projects.
Code Retrieval Is One of the Most Practical Upgrades
Multimodal capabilities may become the highlight of a product launch, but for developers, EmbeddingGemma 2’s improvements in code understanding may be more significant.
On the MTEB Code benchmark, the model’s score increased from 68.76 for the first generation to 78.68, a gain of 9.92 points. This suggests that it is better suited to understanding the purpose of functions, relationships between variables, interface semantics, and similarities between code snippets, rather than merely matching filenames or keywords.
Traditional code search relies primarily on keywords, symbol tables, and simple text similarity. When searching for “the logic that handles failed user logins,” a keyword-based tool may fail to find the relevant function if the code does not contain the exact phrase “login failure.” Vector retrieval can place natural-language descriptions and code semantics into a more closely aligned representation space, making it possible to find implementations whose names are not intuitive.
This is especially valuable for indexing local codebases. Enterprise code, unreleased projects, and developers’ personal directories are often unsuitable for direct upload to third-party services. EmbeddingGemma 2 can perform code chunking, embedding generation, and retrieval locally, then pass the search results to a local or cloud-based generative model for processing.
However, an embedding model cannot replace a complete code-indexing system. It does not inherently solve problems involving symbol references, call chains, version differences, or permission filtering. A usable code-search tool still needs to combine AST analysis, language servers, keyword search, and vector retrieval. EmbeddingGemma 2 is better suited to serving as the semantic retrieval layer, rather than acting as a universal search engine that handles everything.
An 8K Context Window Makes On-Device Multimodal Retrieval Start to Become Practical
EmbeddingGemma 2 expands its context window to 8K tokens, four times that of the first generation.
Google says its on-device processing limits include approximately 5.5 minutes of audio, 29 images, 58 video frames, or interleaved combinations of these inputs. For an embedding model focused on local devices, this context size already covers many practical workflows:
- Building a semantic index for a meeting recording on a phone;
- Searching a photo library for a particular scene using text;
- Retrieving “the architecture diagram that appeared on the whiteboard” from video keyframes;
- Locating an implementation in a local codebase through a natural-language query;
- Searching voice memos, screenshots, and documents within the same knowledge base.
Of course, an 8K-token context window does not mean the model can understand hours of video or an entire large codebase losslessly. Video still needs to be sampled into frames, audio may need to be split into windows, and long documents still require sensible chunking. Once the model’s context expands, the developer’s challenge shifts from “can it process this?” to “how should sampling and chunking strategies be controlled?”
This is also a key difference between multimodal embedding models and generative models. Generative models typically produce text step by step, with latency and cost increasing significantly as context length grows. Embedding models, by contrast, primarily compress input content into vectors and are well suited to batch index construction. A good on-device system can use EmbeddingGemma 2 for fast initial filtering, then pass a small number of candidate items to a generative model for answering, avoiding the need to send all raw data to the cloud for every search.
MRL Reduces the Cost of Vector Databases
EmbeddingGemma 2 supports Matryoshka Representation Learning, commonly known as MRL. It allows developers to truncate the 768-dimensional output vector to 512, 256, or 128 dimensions while preserving as much of the original semantic information as possible.
This may appear to be merely a dimensionality parameter, but it has a practical impact on storage, memory, and retrieval speed in on-device applications.
Suppose a local knowledge base contains 1 million items, with one 768-dimensional vector stored for each item. Using 32-bit floating-point numbers, the vector itself requires approximately 3 KB, before accounting for index structures and metadata. Reducing the dimensionality to 256 can significantly reduce vector storage requirements and improve cache hit rates. For devices such as phones, tablets, and laptops, where both storage and memory are limited, the difference directly affects application usability.
Google says that, combined with MRL, local vector database storage and memory usage can be reduced by up to approximately six times. The actual benefit depends on the vector database, data distribution, and retrieval-accuracy requirements, so this should not be interpreted as meaning that every task can be compressed sixfold without loss.
Developers can view the choice of dimensionality as an engineering trade-off:
- 128 dimensions are suitable for severely resource-constrained scenarios with large data volumes and modest recall requirements;
- 256 dimensions are generally a balanced choice for on-device search;
- 512 or 768 dimensions are better suited to complex semantics, multimodal retrieval, and scenarios with higher accuracy requirements.
The final choice should still be tested on your own dataset rather than copied directly from benchmark results. The optimal dimensionality may be completely different for photo search, codebase search, and enterprise document retrieval.
“Offline RAG” Finally Has a More Complete Set of Building Blocks
The real product value of EmbeddingGemma 2 lies in its potential to become the retrieval component for on-device RAG.
A complete local RAG system typically includes several parts: document or media ingestion, content chunking, embedding generation, vector storage, similarity retrieval, and final answer generation. In the past, the embedding step was often where on-device systems encountered the biggest obstacle: local models either supported text only, were too large, or could not process images and audio at the same time.
EmbeddingGemma 2 now provides a relatively clear path: perform content encoding and vector retrieval on the device while keeping the raw data local. If natural-language answers are also required, the system can decide, based on its privacy policy, whether to send a small amount of retrieved context to a cloud model or run locally alongside a Gemma-series generative model.
This type of architecture is suitable for several clearly defined scenarios:
- Personal knowledge bases: Users’ notes, screenshots, recordings, and documents do not all need to be uploaded to the cloud.
- Internal enterprise search: Sensitive materials can be processed only on enterprise devices or within an internal network.
- Edge-device retrieval: Devices can still search local content when the network is unstable or unavailable.
- Low-latency interaction: Queries can be handled locally first, avoiding the wait caused by a round trip over the network.
- Privacy-first applications: Health records, meeting recordings, code, and personal photos can remain on the device.
However, on-device RAG is not simply a matter of transferring cloud-based RAG to a phone unchanged. Developers still need to handle model updates, incremental index synchronization, device heat, memory reclamation, background task restrictions, and data deletion. Multimodal data is particularly demanding: vectors are only the index, while the original audio, images, and videos still require a reliable local storage and permission system.
Leading Benchmarks Do Not Mean It Wins Every Task
Google describes EmbeddingGemma 2 as a leading sub-1B-parameter multimodal embedding model, saying that it performs strongly on tests such as MTEB Code and MAEB, with some scores surpassing those of larger specialized models.
This claim is reasonably convincing: for embedding models, parameter count is not the only determining factor. Training data, negative-sample construction, modality alignment, and vector-space design all affect final retrieval performance. A smaller model trained with a more targeted objective can indeed outperform a larger general-purpose model.
However, developers should also pay attention to the boundaries of these evaluations. Public benchmarks typically reflect fixed datasets and fixed tasks, and cannot fully represent real-world production environments. Audio, video, and document retrieval are particularly sensitive to data formats, languages, noise, chunking methods, and recall strategies. Google’s model-card results can serve as a starting point for model selection, but they cannot replace offline evaluation on your own data.
There is another practical issue: runtime support across the multimodal ecosystem may not be as mature as the text pipeline. A model’s ability to process images and audio only means that the model itself has those capabilities. Compatibility differences may still exist across model-file conversion, hardware acceleration, input preprocessing, and vector-database integration. When choosing LiteRT, MediaPipe, or another inference framework, developers need to validate the text, image, audio, and video pipelines separately rather than assuming that full multimodal deployment is complete after getting a single text demo to work.
This Release Shows Google Betting on “Local Infrastructure”
EmbeddingGemma 2 is released under the Apache 2.0 license, allowing developers to use, modify, and redistribute it commercially as long as they comply with the license requirements. For startups and application developers, this offers more control over costs, data, and deployment than solutions that can only be accessed through cloud APIs.
Over the past several years, Google has continued to advance Gemma, LiteRT, MediaPipe, and Android AI Edge. Viewed on its own, EmbeddingGemma 2 is simply an embedding model. Viewed as part of the broader ecosystem, it serves as the “indexing layer” of on-device AI. Generative models are responsible for writing answers, embedding models locate the data needed to produce those answers, and on-device runtimes bring the entire workflow onto consumer devices.
The competitive advantage in this area is not just about model scores. The company that enables developers to complete model conversion, quantization, hardware acceleration, and application integration more quickly is more likely to become the default infrastructure for mobile AI applications. Google has Android and Pixel devices as validation environments, an advantage that open-source model vendors may not necessarily possess.
For developers, three aspects of EmbeddingGemma 2 are particularly worth watching. First, it brings the deployment threshold for multimodal embeddings into a range that phones can realistically handle. Second, its improvements to code retrieval and local RAG are relatively direct. Third, its modular design and MRL support allow the model to be tailored to different devices and scenarios.
But it is not the best answer for every application. If a business requires extremely high recall accuracy, complex cross-language reasoning, or unified large-scale cloud indexing, a larger cloud-based embedding model may still be more appropriate. If the goal is only simple keyword search, deploying a 740-million-parameter multimodal model may also be overengineering.
A sensible way to use it is as the on-device retrieval layer: perform data encoding and candidate retrieval locally first, then decide where to place the subsequent generation stage based on privacy, latency, and cost requirements. For developers looking to build offline search, privacy-first RAG, coding assistants, or cross-modal personal knowledge bases, this update is worth downloading and testing in practice. It is best to start with your own datasets and device matrix rather than looking only at the memory figures from the product launch.
References
- IT Home: Google Launches EmbeddingGemma 2: Supports Multimodality, with the Quantized 740-Million-Parameter Model Running on Phones with Just 191 MB of Memory — Introduces the model’s release details, parameter scale, on-device memory usage, and core capabilities.
- Hugging Face — Can be used to find open-source model weights, model cards, and community deployment information; the specific version should be confirmed against the official EmbeddingGemma 2 release page.