AI Paper Tool Is Here: Say Goodbye to Searching for a Needle in a Haystack of Literature
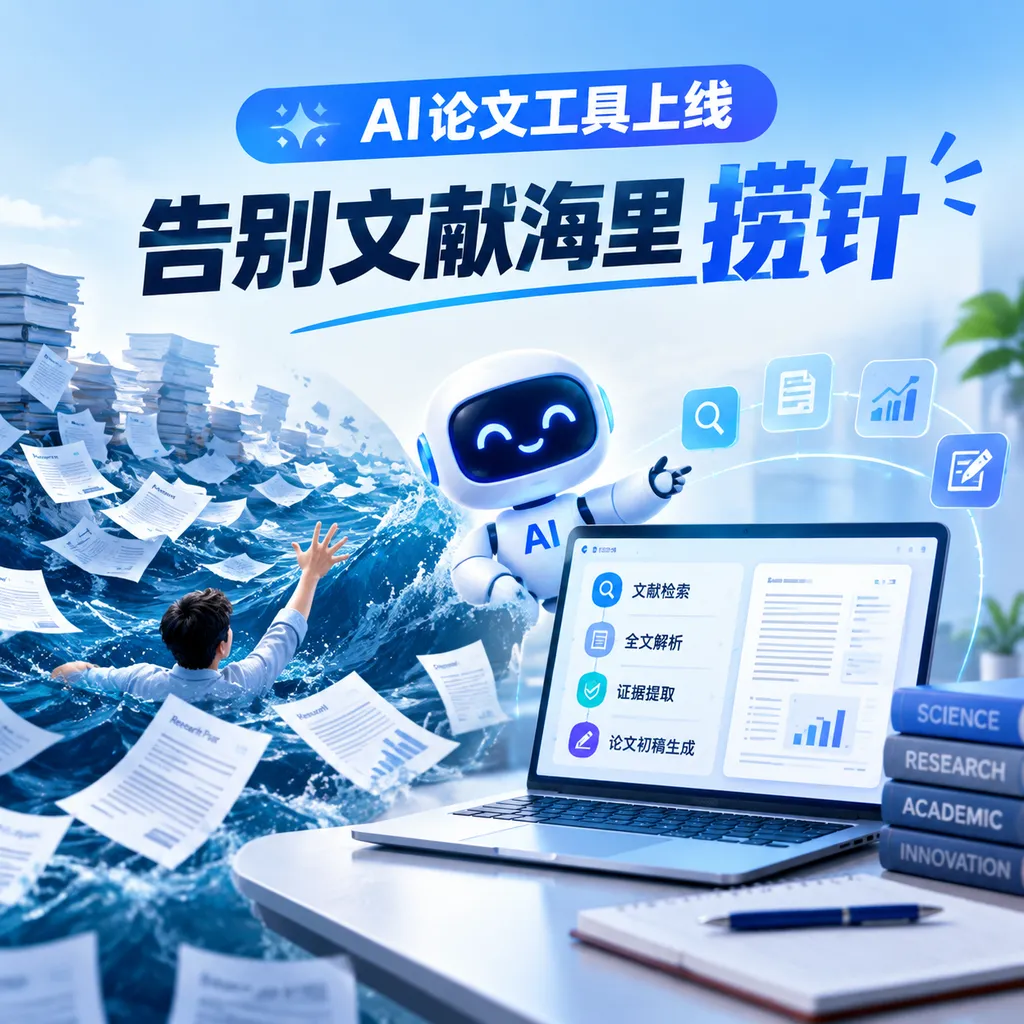
An AI paper tool for research and engineering teams was recently launched. It uses a multi-agent workflow to search the literature, extract full texts, organize evidence, and generate initial paper drafts. What it truly solves is not “helping you write a few paragraphs,” but organizing scattered research materials into a traceable chain of argument.
AI Research Paper Tool Launches, Finally Saving Developers from Repeatedly Pressing Ctrl+F in Papers
An AI research paper tool for researchers, engineers, and innovation teams was recently launched. It breaks literature search, paper reading, evidence extraction, citation management, and first-draft generation into multiple stages, then assigns different AI agents to complete them collaboratively.
The goal of this type of product is not to have a model “write an entire paper with one click,” but to handle the most time-consuming and error-prone part of research: finding truly relevant content among hundreds of papers, verifying the sources of conclusions, and organizing scattered evidence into a research draft that can be further revised.
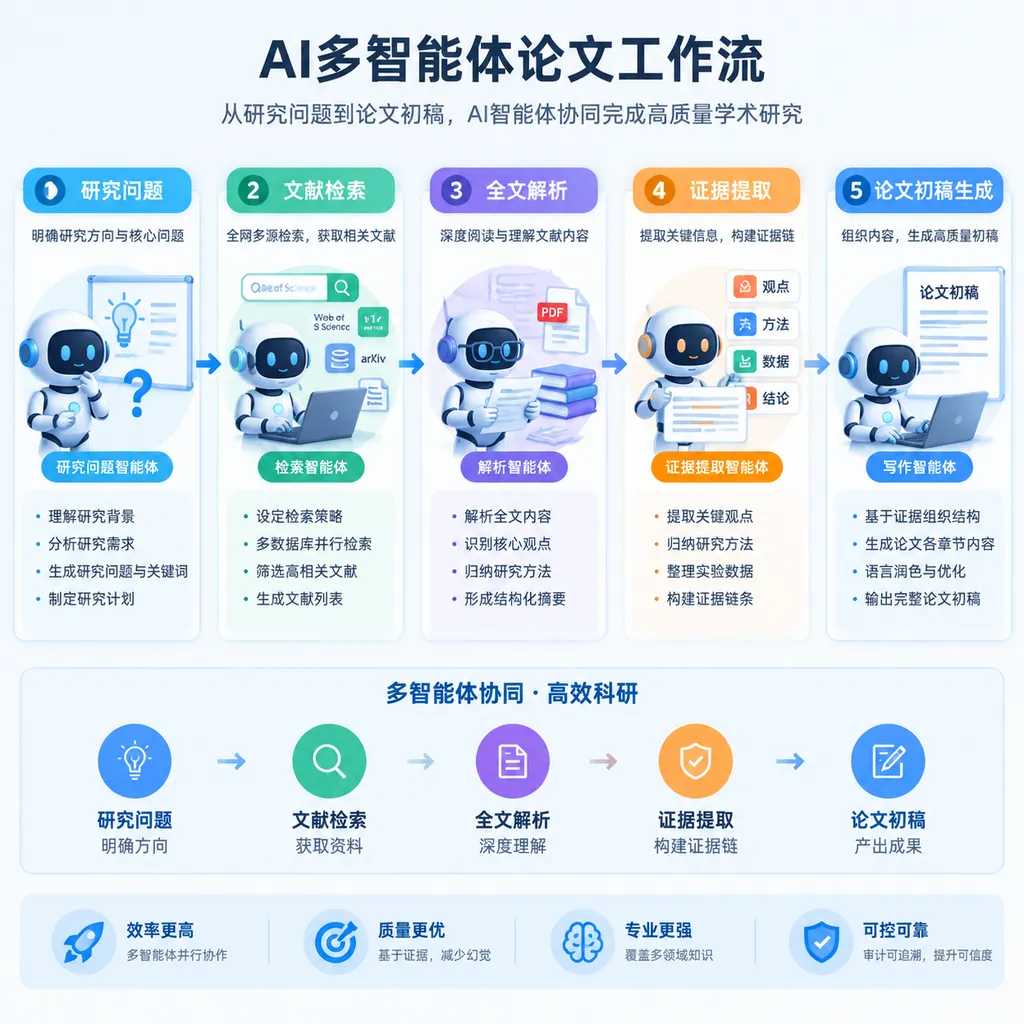
According to its public materials, Gatsbi uses a sophisticated multi-agent workflow covering research idea discovery, paper generation, systematic literature reviews, and meta-analyses. The product also offers desktop and web versions. Users can start with a research topic, generate candidate research directions, expand them into concrete proposals, and finally produce a draft paper or patent disclosure document.
The Real Change: From “Asking a Model” to “Running a Workflow”
In the past, developers typically used large language models to assist with paper reading by uploading a PDF and asking, “Please summarize this paper.” This works for individual papers, but when conducting a systematic review or technical survey, three problems quickly emerge: the context window is insufficient, citations cannot be verified, and comparisons across papers are inconsistent.
The idea behind a multi-agent workflow is to break an ambiguous research task into multiple interconnected subtasks. For example:
- Search agent: Expands keywords based on the research question and searches academic databases for candidate papers;
- Screening agent: Ranks and filters papers according to topic relevance, research methods, publication date, and inclusion criteria;
- Reading agent: Locates key sections such as the abstract, methodology, experimental results, and limitations instead of reading only the title and abstract;
- Extraction agent: Organizes sample sizes, variables, evaluation metrics, experimental results, and other information into structured tables;
- Synthesis agent: Compares conclusions across papers and identifies consensus, conflicts, and research gaps;
- Writing agent: Generates a cited first draft based on the evidence table and outline;
- Review agent: Checks whether citations correspond to the claims, whether assertions go beyond the original text, and whether there are logical jumps between paragraphs.
The difference between this and an ordinary chatbot is similar to the difference between “temporarily asking someone to help find information” and “having a small research team conduct a study according to a defined process.” The former relies on the user to keep asking questions, while the latter emphasizes task status, role assignment, and intermediate outputs.
However, multi-agent does not mean that every step is handled by a different large model. A more realistic implementation is for one or more models to play different roles through different system prompts, tool permissions, and output formats. The real product value often lies not in the word “agent,” but in the search interfaces, PDF parsing, citation tracking, structured data storage, and failure-retry mechanisms.
Solving Developers’ Most Frustrating Literature Search Problem
For developers working in AI, software engineering, bioinformatics, and human-computer interaction, literature search is often not about failing to find papers, but about failing to find a particular sentence within them.
A paper dozens of pages long may discuss datasets, model architectures, training details, ablation experiments, and limitations at the same time. The title or abstract can only tell you roughly what the paper did; it cannot directly answer specific questions such as:
- What dataset did the method use, and how large was the sample?
- What was the baseline version in the comparison experiments?
- Did the improvement in the metric come from the model itself or from additional data cleaning?
- Do the reported results hold across different tasks?
- Have the limitations claimed by the authors been confirmed by subsequent research?
The traditional approach is to download a PDF, search for keywords, and manually copy the content into notes or spreadsheets. The problem is that PDF layouts, two-column formatting, equations, and scanned pages can make search results unreliable. Even when a keyword is found, the surrounding context may be truncated, and the relationship between the citation and the conclusion still requires manual verification.
The core value of this tool is that it allows users to ask structured questions directly, after which the system extracts answers from multiple papers in batches. For example, users can ask it to compare the datasets, models, experimental metrics, and limitations in 30 papers, ultimately producing an editable evidence table rather than 30 mutually independent summaries.
More importantly, extracted results need to retain their sources. Ideally, every number and judgment should link back to a specific passage in the original paper. Only then are the results suitable for research notes, technical reports, or paper drafts, while also allowing researchers to verify them item by item.
From Research Question to First Draft in Just a Few Steps
The publicly described product workflow can be roughly divided into three stages.
Step 1: Enter a Research Topic and Generate Candidate Directions
The user first enters a research topic or field. The system combines this input with existing papers to generate multiple possible research ideas, providing a problem definition, implementation plan, and relevant references for each idea.
This step is particularly useful for engineers. Many technical topics are not lacking in ideas, but in the ability to quickly assess existing work: Has a particular direction already been thoroughly studied? Is the supposed innovation merely a change of dataset? Which methods can be reproduced with the available computing resources and data?
AI can first provide a candidate map, but an “originality score” can only serve as a lead, not a conclusion. A model cannot guarantee that it has not missed the latest papers, nor can it replace the researcher’s judgment about the value of a problem.
Step 2: Expand the Proposal and Fill in the Technical Details
After selecting a direction, users can continue expanding the proposal and ask the system to supplement the methodology, experimental design, data requirements, and evaluation methods. At this point, the agent functions more like a research assistant, breaking a conceptual idea down into executable tasks.
For developers, the output at this stage should be checked primarily for reproducibility. Does the proposal specify the source of the training data, the baseline models, the hyperparameter ranges, the evaluation metrics, and the failure conditions? If it only offers vague descriptions such as “use an advanced model to improve performance,” the resulting paper will still lack research value.
Step 3: Generate a Draft Paper or Patent Disclosure Document
Once the research plan and relevant evidence are ready, the system can generate a first draft containing a section structure, equations, figures, tables, in-text citations, and references. It supports methodological papers, experimental studies, case studies, and systematic literature reviews, connecting research ideas, evidence, and writing.
The term “first draft” must be understood accurately here. This is not a finished paper ready for submission, but a working document in which the information has been organized and the structure has been established. Researchers still need to add real experiments, verify every citation, rewrite key arguments, and assume ultimate academic responsibility.
Where Does It Have an Edge over Ordinary AI Writing Tools?
There are already many AI academic tools on the market. Products such as Paperguide focus on searching paper libraries, cross-paper question answering, evidence tables, and citation management. Happycapy combines database connections, batch abstract screening, full-text extraction, and ongoing monitoring into a research workflow. Gatsbi places more emphasis on a continuous process from research ideas to paper and patent drafts.
The common trend among these products is a shift from “writing plugins” to “research operating systems.” They are no longer responsible only for polishing sentences, but are attempting to manage the materials, tasks, and evidence involved in the research process.
The new tool’s main differentiators are multi-agent collaboration and end-to-end generation. Users do not need to manually organize a complete literature library before handing it over to a writing model. Instead, they can start with a research topic and allow search, screening, extraction, synthesis, and writing to unfold step by step.
However, end-to-end workflows also introduce new risks. The longer the process, the greater the possibility of error propagation. If a key paper is missed during the search stage, subsequent evidence synthesis will be based on incomplete data. If full-text parsing goes wrong, numbers in the table may be written into the final draft. If citation matching is inaccurate, an apparently rigorous argument may lose its credibility.
Therefore, these tools should not be evaluated solely by how fluent the generated text is. Four metrics matter more:
- Search recall: Can it find genuinely relevant studies, especially studies that contradict one another?
- Evidence traceability: Can each conclusion and data point be located in the original text?
- Cross-paper consistency: Can it consistently compare metrics and experimental conditions across different papers?
- Human controllability: Can users modify inclusion criteria, remove incorrect evidence, and regenerate only selected sections?
It Still Cannot Replace Researchers
The aspect of AI research paper tools most likely to be misunderstood is that “automatic generation” may look like “automatic completion.” In reality, the hardest parts of research are not writing sentences, but deciding which questions are worth studying, which evidence can be compared, and whether a conclusion actually holds.
A system may extract “a 3% increase in accuracy” from a paper, but it may not automatically determine whether the two experiments used the same data split. It may summarize the methodological advantages claimed by the authors, but fail to notice that the paper’s statistical tests were insufficient. It may generate a logically coherent related-work section, but cannot guarantee that it has not turned a correlation into a causal relationship.
In high-risk fields, human review remains essential. In particular, in medical, financial, materials, and safety research, any unverified experimental result, fabricated citation, or incorrect data may cause losses far greater than the time saved.
A more reliable approach is to treat AI as an auditable research assistant: let it expand the search scope, standardize extraction formats, flag contradictions, and build the first draft; let researchers define the problem, validate experiments, assess evidence, and take responsibility for the final wording.
What Comes Next for Multi-Agent Research Paper Tools
In terms of product development, the next stage of competition will not simply be about who can generate the longest paper. It will center on research data and workflows.
The first area is database connectivity. Truly valuable tools need to work with arXiv, Semantic Scholar, PubMed, institutional subscription databases, and users’ own Zotero and Mendeley libraries. Only by covering multiple sources can search results avoid being limited to the index of a single database.
The second is continuous research. A research topic does not end after a single generation. Ideally, a system should preserve the research question, inclusion and exclusion criteria, papers already read, and current evidence conclusions; periodically search for new papers; and flag conclusions that may need to be updated.
The third is reproducibility. For engineering teams, it would be better to export structured evidence tables, BibTeX, CSV files, or experimental hypotheses rather than merely exporting a visually polished document. The more easily the research process can be saved and replayed, the more reliable team collaboration and subsequent review will be.
Finally, these tools need to connect with actual development environments. Methods from papers ultimately often need to enter code repositories, experiment platforms, and evaluation pipelines. In the future, research agents may do more than generate text: they may create experiment tasks based on the literature, configure baselines, run evaluations, and feed the results back into the draft. This also means that access control, data isolation, and experiment auditing must be established at the same time.
Overall, the launch of this tool represents a clear shift in AI academic products: from writing assistance toward evidence production driven by multiple agents. It is best suited to people who already have a clear research question but are being slowed down by literature screening, full-text reading, and information organization.
It will not make papers automatically correct, but it may compress the most mechanical and time-consuming parts of the process into a few hours. For developers, the question worth watching is not whether AI can write a paper for you, but whether it can help you find the source of every conclusion more quickly and ensure that every research judgment is backed by verifiable material.