Huawei AI Connects 25 Games
Huawei AI completed challenges in 25 games through recursive self-improvement, using 56% fewer actions on average than humans. In some matches, it even stopped calling the large language model after taking a 21–0 lead. What truly deserves attention is not the completion of the games, but how the model distilled trial-and-error experience into executable strategies.
Huawei AI Tackles 25 Games: 56% Fewer Actions Than Humans
Huawei AI recently completed challenges across 25 games using a recursive self-improvement (RSI) process. According to public reports released on October 12, 2026, the system used 56% fewer actions than human players, and in some games even achieved results of 21:0.
More interestingly, the AI did not rely on a large model to make real-time decisions throughout the entire process. After completing strategy searches and summarizing its experience, the system could solidify verified behaviors. During subsequent execution, it did not even need to call the large model.
The value of this development does not lie in AI winning another batch of simple games. Games have long served as test beds for agent research. What developers should really focus on is whether a model can turn repeated failures into better strategies for the next round, and whether it can gradually switch from costly reasoning processes to low-cost execution programs.
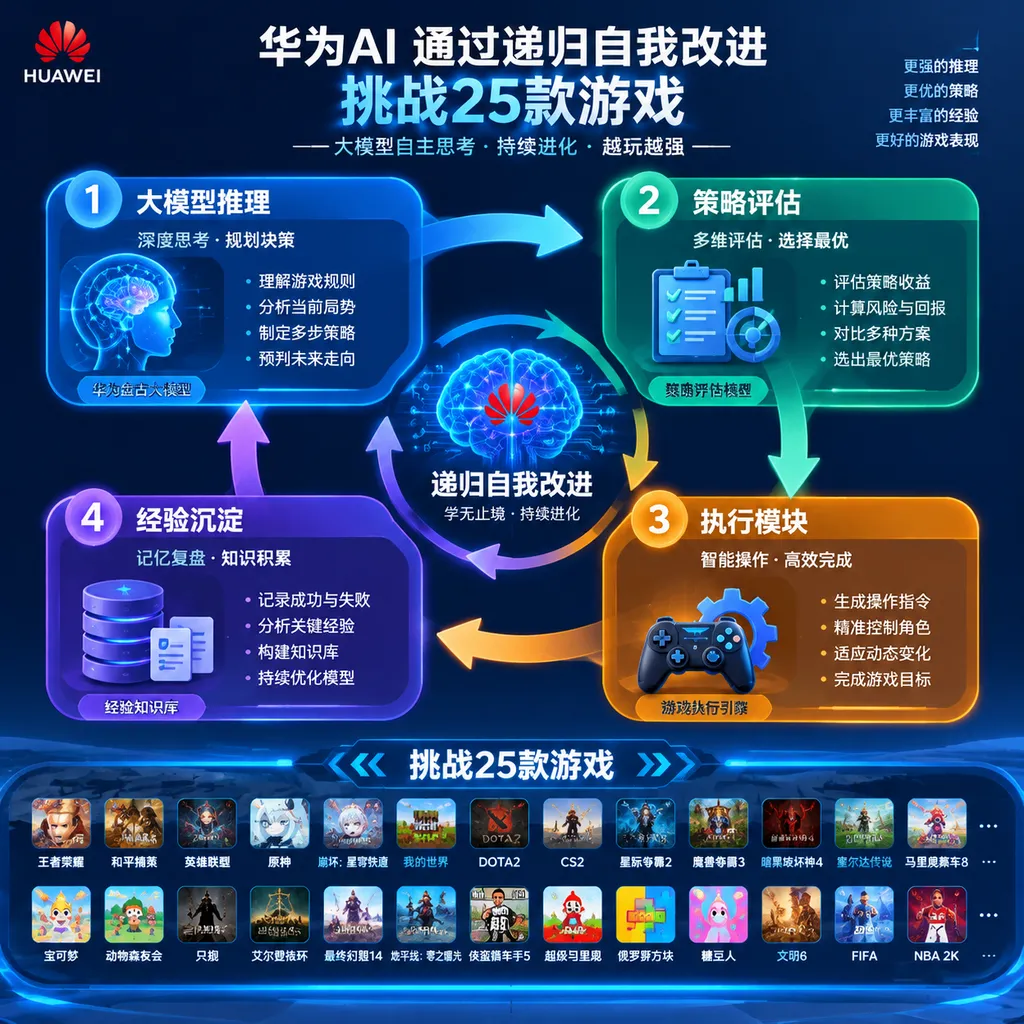
Not Making the Model Think More Times, but Making It Modify Its Own Solution
Traditional large-model agents typically follow a workflow like this: read the game state, call the model for analysis, and output an action; after receiving the new state, repeat the process.
This approach is simple, but expensive. Every step requires context assembly, reasoning, and action parsing, so latency and token consumption increase linearly with the number of actions. More troublesome is that errors made in the previous round may not be reliably remembered by the model. It may have just crashed into an obstacle because it was rushing, only to make a similar choice in the next step.
The idea behind RSI is different. Instead of treating the model as a controller responsible only for real-time reactions, it involves the model in rewriting the strategy itself:
- Execute the current strategy first: Attempt to complete the task in the game environment while recording actions, states, and results.
- Evaluate the causes of failure: Determine whether the problem was incorrect path planning, unreasonable resource allocation, or failure to identify the game rules.
- Generate an improvement plan: Have the model propose a new strategy, rule, or program logic.
- Verify it in the environment: Run the new strategy and observe whether it actually improves the win rate or reduces the number of actions.
- Retain effective experience: Accumulate verified strategies so they can be called directly for subsequent tasks.
This can be understood as “the model writes the draft, the environment acts as the judge, and the program is responsible for remembering the correct answer.” Each round is not merely a matter of answering the question again; it modifies the problem-solving method.
In pseudocode, the structure is roughly as follows:
policy = initialize_policy()

for iteration in range(max_iterations):
    result = run_game(policy, environment)
    score = evaluate(result)

    feedback = analyze_failure_or_bottleneck(result, score)
    candidate = propose_policy_update(policy, feedback)

    candidate_result = run_game(candidate, environment)
    if evaluate(candidate_result) > score:
        policy = compile_or_store(candidate)

return policy
The key element here is not the loop itself, but compile_or_store. If the system gives the historical trajectories back to the large model every time it executes, it is merely “remembering more” rather than actually becoming faster. Only when effective strategies are compressed into rules, action templates, search paths, or lightweight controllers has the model completed the transition from reasoning to execution.
What Does It Mean That the Large Model Was No Longer Called After 21:0?
One particularly representative detail in the reports is that, after achieving a score of 21:0 in some games, the AI no longer needed to call the large model.
This sounds like a performance metric, but it is actually more like a signal about system design.
In game agents, large models are well suited to tasks such as:
- Quickly building a task model when the rules are not yet understood;
- Proposing possible courses of action when facing unfamiliar situations;
- Explaining the causes of failure and revising the plan after consecutive failures;
- Making high-level trade-offs among multiple candidate strategies.
However, large models are not suitable for handling every low-level action. For example, moving a character to the right, waiting two frames, releasing a skill, and confirming a collision again do not need to be reasoned through by the model every time once the rules are clear.
A truly efficient architecture should resemble a hierarchical control system:
- Planning layer: The large model understands the goal and formulates the strategy;
- Skill layer: The strategy is broken down into reusable action skills;
- Control layer: Deterministic programs or small models handle high-frequency operations;
- Evaluation layer: Results are continuously checked, with issues escalated back to the planning layer when necessary.
If a game has already been verified to be winnable by following a fixed path, continuing to call the large model is simply wasteful. Removing the large model from the real-time loop does not indicate reduced capability. It may instead show that the system has solidified that capability into cheaper and more stable modules.
From an engineering perspective, this is somewhat similar to compiler optimization. The first execution may require an interpreter to analyze the code line by line. Once hot paths have been identified, they can be compiled into machine code. RSI gradually transforms the model’s reasoning process into strategy code or action programs.
“56% Fewer Actions” Is More Worth Examining Than “Winning”
Simply comparing wins and losses provides limited information. A system with stronger prior knowledge, more training data, or unlimited retries may be able to win many simple games.
The number of actions is closer to an efficiency metric. Suppose a human player needs 100 actions to complete a task, while the AI needs only 44. The AI may then be better at path selection, action consolidation, and failure avoidance. Especially in games where resources are limited and actions carry a cost, reducing ineffective actions usually indicates better planning ability.
However, this figure cannot be directly equated with “AI is 56% smarter than humans.” Developers need to pay particular attention to several conditions of comparison:
- Whether the human players were familiar with these games;
- Whether the AI had seen the rules, maps, or reward functions in advance;
- Whether the action count included waiting, repeated clicks, and ineffective actions;
- Whether the AI was allowed to pause, backtrack, or repeatedly experiment;
- Whether humans and AI operated under the same visual, input, and time constraints;
- Whether the difficulty and types of the 25 games were sufficiently diverse.
If the humans were encountering the games for the first time while the AI could run hundreds of rounds in the environment and save the optimal strategy, the result is closer to “an automated search system defeating a one-time player” than to a comprehensive comparison of general intelligence.
Therefore, 56% is a result worth noting, but a complete experimental protocol is still needed, including the task list, number of repeated trials, training and test split, per-game budget, and performance after transferring the strategy to new games.
The Difficulty of RSI: It Can Easily Turn “Trial and Error” into Cheating
Recursive self-improvement sounds powerful, but it is difficult to implement in real systems. The first challenge is the evaluator.
If the only evaluation metric is the final score, the model may discover opportunistic shortcuts. For example, in some games, repeatedly resetting the game state, trapping an opponent, or exploiting an environmental bug may all produce a higher score. The system may think it has learned a strategy when it has actually only learned how to exploit loopholes in the scoring function.
Therefore, the evaluator must examine not only the outcome but also the process:
- Whether operational constraints were violated;
- Whether vulnerabilities specific to the test environment were exploited;
- Whether the strategy remains effective on a different map;
- Whether it can be reproduced reliably within a limited number of attempts;
- Whether it truly reduces ineffective actions rather than gaining an advantage by bypassing measurement.
The second challenge is error accumulation. RSI saves effective experience, but if the evaluator makes a misjudgment, an incorrect strategy may enter the memory bank and become the basis for the next round of optimization. After multiple iterations, the system may drift further and further off course.
The third challenge is strategy bloat. The model may continuously add exception rules. While this may cover more situations in the short term, it eventually creates a strategy set that is difficult to maintain. From an engineering perspective, strategies need to undergo regular compression, conflict detection, and regression testing. Otherwise, so-called self-improvement may amount to nothing more than continuously stacking patches into the code.
Implications for Developers: Do Not Put the Large Model in Every Loop
The first practical lesson from this work is to reconsider the granularity at which agents call models.
Many Agent projects place the large model in the main loop: every time a state is read, the model is called once. This approach is fast to develop, but after deployment it typically leads to three problems: high latency, unpredictable costs, and unstable behavior.
A more suitable approach is to divide calls into two categories:
1. Low-Frequency Strategy Calls
These handle goal decomposition, route selection, anomaly explanation, and strategy updates. They can use more capable and expensive models, but do not need to be called every frame.
2. High-Frequency Action Execution
These handle clearly defined action sequences, tool calls, and state-machine transitions. They should use deterministic code, rule engines, or small models wherever possible to ensure low latency and reproducibility.
In real projects, each model output can be divided into two parts: one part is the current action, and the other is a reusable skill description. For example, when the model first determines that it needs to “collect resources first, then bypass obstacles to reach the exit,” the system should attempt to convert this plan into a skill with preconditions, execution steps, and failure fallbacks, rather than retaining only the original text.
At the same time, all strategy updates should undergo offline replay and regression testing. A new strategy should not be pushed directly into production simply because it achieved a higher score once. In systems involving real users, real funds, or real devices, exploration and execution must be isolated.
This Is Not the End of Game Intelligence, but a Demonstration of Agent Engineering
Huawei AI’s completion of challenges across 25 games using RSI is significant not because “AI can now play games,” but because large-model agents are beginning to move from “relying on reasoning at every step” toward “reason first, solidify the result, and then execute it at low cost.”
This path is closer to productization than simply expanding the context window or increasing model parameters. Real-world tasks are often not one-off question answering, but long-running processes: robots need to repeatedly perform actions, coding agents need to continuously debug, data agents need to repeatedly query and verify, and enterprise automation systems need stability rather than occasional flashes of insight.
Of course, there is still a long distance between 25 games and the real world. Game rules are clear, feedback is timely, and rewards are easy to calculate, while real-world tasks are full of ambiguity, noise, and irreversible consequences. Whether AI can transfer strategies learned in games to unfamiliar environments, and whether it can remain cautious in situations where errors are costly, will be the real test of the next stage.
But the direction is already clear: a mature Agent should not always have the large model serve as the steering wheel. A better system lets the model change the route while the program drives steadily along it; when the environment changes, the problem is handed back to the model for replanning.
For developers building agent systems, this is more worth trying first than simply “switching to a larger model.”
References
- Reference material cited in the article: “Huawei AI Beats 25 Games with RSI! 56% Fewer Actions Than Humans,” which reports on Huawei AI’s 25-game challenge, the comparison of action counts, and the fact that the large model stopped being called after a 21:0 result.
- GitHub related project search page: Used to further explore engineering practices related to recursive self-improvement, game agents, and strategy iteration; this does not represent an official Huawei project page.